A recipe search needs to find relevant recipes even when a question uses different words from the stored instructions. Vectorization turns text into numerical vectors so a similarity search can compare meaning rather than exact wording. An embedding model performs the conversion. section 14.3 section 14.10.1
A two-dimensional flavor map makes the idea tangible: a poke-bowl recipe may sit near sushi. Real recipe embeddings are not coordinates for taste; they encode language relationships across thousands of dimensions. At retrieval time, the question must be embedded with the same model used for the stored recipes. Cosine similarity then favors vectors pointing in similar directions, even when their text differs. section 14.3 section 14.10.1
In a recipe retrieval workflow:
- Ingest recipes, split text into chunks, generate embeddings, and update the vector database. Airflow can schedule and monitor these tasks. section 14.11
- Embed the user’s question and search the database for relevant recipe text. section 14.10.1
- Pass the question and retrieved recipes to an LLM to generate an answer grounded in that context. section 14.3
Configure a recipe collection
A Weaviate collection can set `vectorizer_config=[get_vectorizer_config(embedding_model)]`. For `text-embedding-3-large`, the configuration function selects `Configure.NamedVectors.text2vec_openai` when `OPENAI_CONN_TYPE` is `openai_api`, or `text2vec_azure_openai` when it is `azure`. The Azure route also reads its endpoint and resource name from environment variables. This keeps the embedding-model choice explicit while allowing either connection route. section 14.6.1
Chunk size affects retrieval: oversized chunks make a source harder to pinpoint, while undersized chunks can produce redundant results and inefficient queries. Choose an embedding model for the intended provider ecosystem, and use it consistently for stored text and questions. section 14.11 section 14.6.1 section 14.10.1
Figure 14.17 In the retrieval workflow, we can embed a user’s question and perform a similarity search in the database using cosine similarity. The vector database returns the documents that are most relevant to the question.
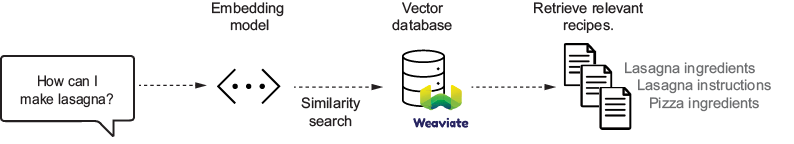
The retrieval diagram traces a question from embedding through similarity search to the most relevant documents. section 14.10.1

















