Vectorization expresses loads, computation, stores, and masking over a block of elements rather than one scalar at a time. A vectorized operation is not necessarily a single hardware instruction. section 2.1.1
Figure 2.1 CUDA assigns one thread to each element, so two blocks of four threads (T0-T3) each compute four scalar additions individually. Triton assigns one program instance to each whole block, so program P0 computes z[0:4] = x[0:4] + y[0:4] and program P1 computes z[4:8] = x[4:8] + y[4:8] as single block-level operations.
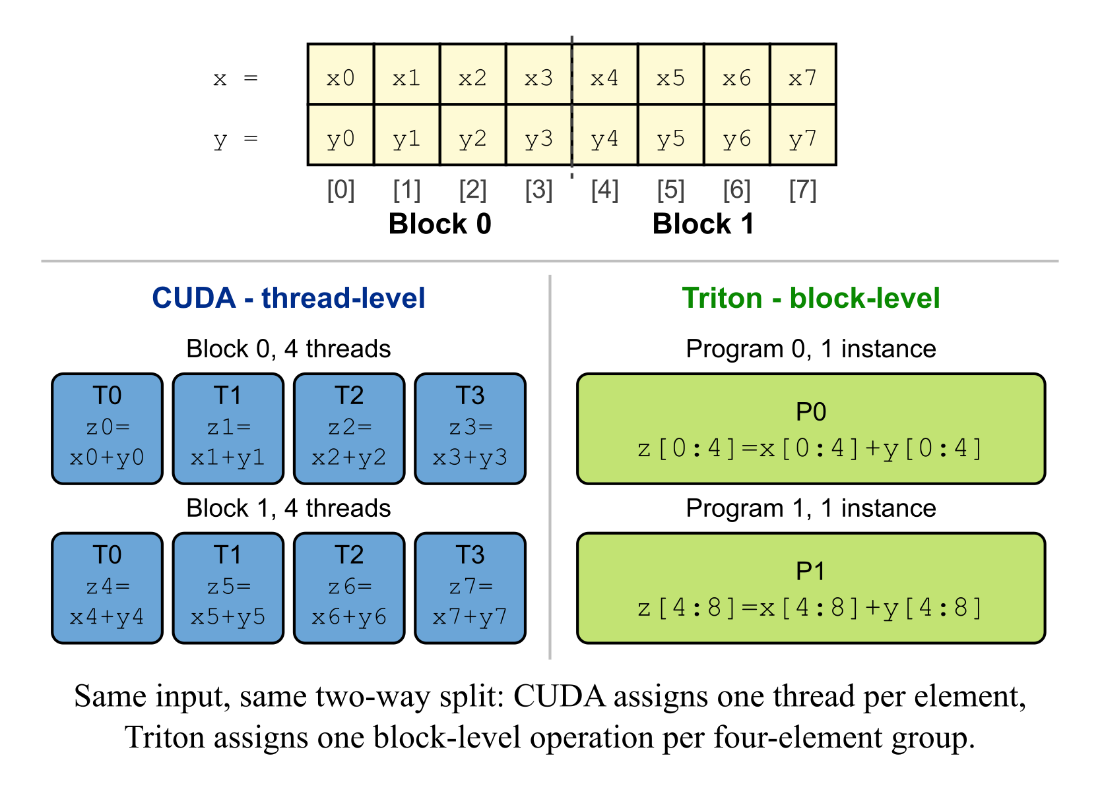
The comparison shows how Triton expresses the same additions as block-wide operations instead of assigning each element to an individually managed thread. section 2.1.1
Vector addition
For vectors of eight elements and a block size of four, each Triton program instance computes four additions, such as z[0:4] = x[0:4] + y[0:4]. section 2.1.1





















