An intercept, also called a neural-network bias, is a learned number added to a weighted sum. It shifts a node’s output independently of its weighted inputs, giving the network flexibility to move an activation function up or down. A line that must pass through 0,0 can gain a different intercept when a constant is added. section 9.15
Biases appear at specific points in a layer’s calculation:
- The layer first multiplies its input vector by a weights matrix and sums the results. section 11.25
- It then adds one learned bias value for each output dimension, shifting each output up or down. section 11.25
- A nonlinear activation such as ReLU can follow the adjustment, replacing negative values with zero. section 11.25
- A later project-down layer adds its own bias vector before the feed-forward result joins the residual connection. section 11.26
A bias vector in a project-up layer
Suppose weight multiplication produces [1.5921, 0.3436, -0.5260, 1.7674, -0.4769, -1.6255, 0.2961, 0.3492]. Adding [0.1, -0.05, 0.2, -0.15, 0.0, 0.1, -0.2, 0.05] adjusts each corresponding value. ReLU then keeps positive results and changes negative results to 0. The eight bias values match the layer’s eight output dimensions. section 11.25
Figure 11.46 Calculations for adding bias to the output
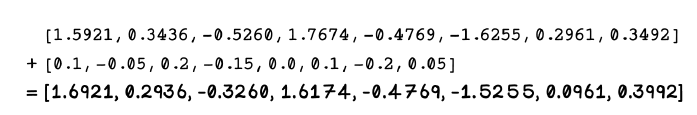
Use the calculation figure to trace how each project-up output changes when its matching bias value is added. section 11.25






