Preprocessing prepares data and intermediate representations before model execution. Depending on the task, it may encode images and prompts, resize and normalize inputs, or convert them into the model’s expected format. section 15.5 section 15.7.3
Common preprocessing roles include:
- Encode an image and a text or point prompt into embeddings before combining them in a multimodal model. section 2.4
- Prepare images and segmentation masks by resizing, normalizing, and converting them to tensors. section 15.7.3
- Filter noisy captions and generate synthetic captions when preparing training data for image-text learning. section 2.4
Segmentation inputs
A Segformer training loop passes CT-image and mask paths to SegformerImageProcessor, then feeds the resulting pixel values and labels to the model. With SAM, set_image preprocesses a photograph while a point prompt is encoded separately before prediction. section 15.5 section 15.7.3
Figure 2.9 Conceptual diagram of BLIP caption generation
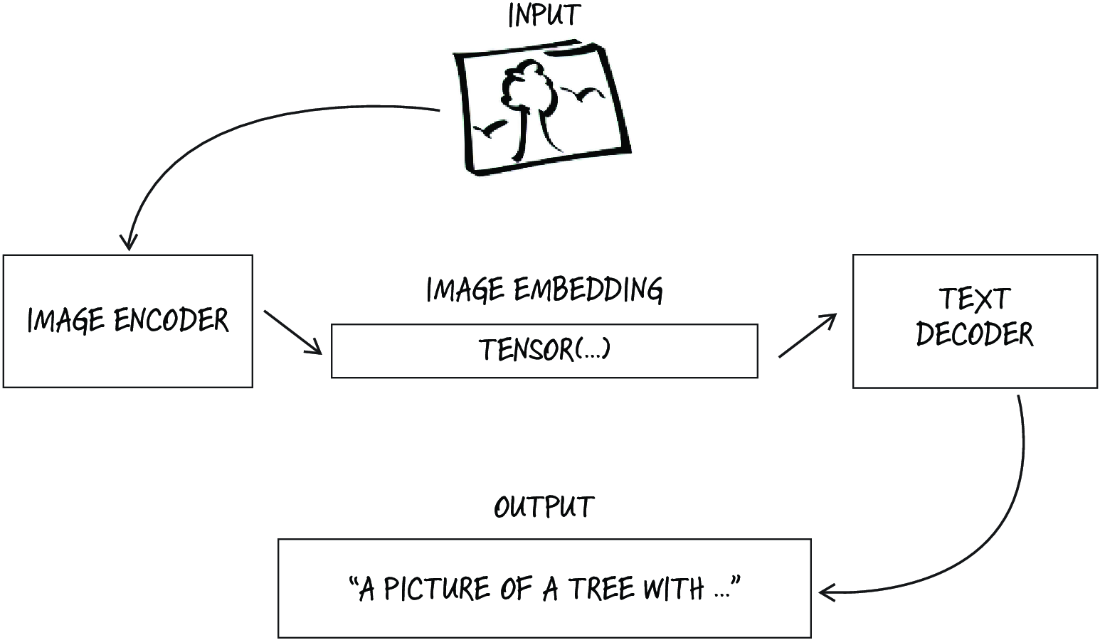
Use the diagram to follow how BLIP separates image encoding from text decoding during caption generation. section 2.4





















