A convolutional kernel, or filter, is a small grid of learned weights that slides across an image. At each location, a dot product compares the weights with local pixels; the resulting feature map highlights where the learned pattern appears. Reusing the same filter across locations reduces the number of parameters and supports recognizing patterns in different positions. section 2.5.1
From edges to object parts
In AlexNet, early filters can respond to horizontal or vertical edges in a cat image. Later layers combine simpler responses into contours and recognizable parts. Filter sizes progress from 11 × 11 in early layers to 5 × 5 and then 3 × 3 deeper in the network. section 2.5.1
Figure 2.3 The AlexNet architecture (cropped in the original paper). The numbers indicate spatial dimensions and channel depth at each stage. The input image (224 × 224 × 3 RGB) passes through a series of convolutional and pooling layers that progressively reduce spatial resolution (224→55→27→13) while increasing channel depth. Early downsampling is driven by the first convolutional layer (11 × 11 filters with a stride of 4), followed by max pooling layers (3 × 3 windows with a stride of 2) that further reduce spatial dimensions. The stride determines how far a filter moves across the input at each step, controlling how densely the image is sampled and how quickly spatial resolution is reduced. Filter sizes (11, 5, 3) are depicted as cubes and define the local receptive field of each convolution. The two horizontal streams reflect the model’s original two-GPU training setup, where feature maps were split across devices (e.g., 48 + 48 = 96 channels). The fully connected layers (4096 neurons, implemented as 2048 + 2048 across GPUs) feed into a 1000-way output for ImageNet classification. Used with permission granted by the lead author (Alex Krizhevsky).
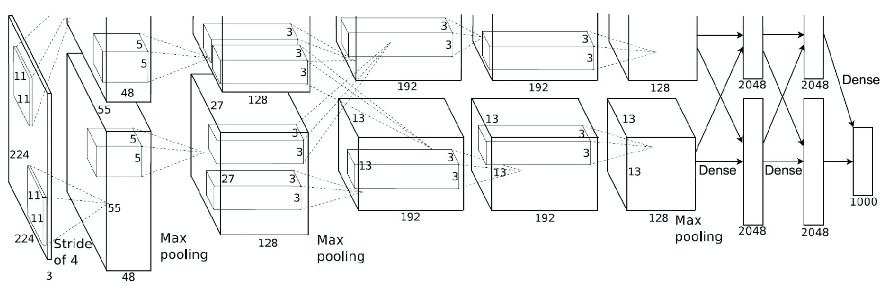
The architecture diagram shows filter sizes and strides alongside the changing spatial dimensions and channel depth. section 2.5.1










