A learning rate is the step-size setting used when optimization moves neural-network parameters such as weights and biases. Training repeatedly adjusts these parameters to reduce a loss and bring predictions closer to known targets. In gradient descent, the update moves opposite the gradient; the learning rate controls how far that move goes. section 8.4 section 8.4.3
The gradient supplies the direction of steepest local decrease, while the learning rate supplies the scale. A larger value can make optimization progress faster, but it can also overshoot the minimum. The rate is therefore a tunable hyperparameter rather than a learned model parameter. section 8.4.3
A typical PyTorch training step applies the learning rate through the optimizer:
- Create a loss function and an SGD optimizer, setting the rate with `optim.SGD(model.parameters(), lr=0.02)`. section 9.2.3
- For each minibatch, compute model scores and loss, clear old gradients, backpropagate with `loss.backward()`, and update parameters with `optimizer.step()`. section 9.2.3
- Repeat the loop across epochs while monitoring whether the loss decreases and predictions improve. section 9.2.3
Classifying Statsville residents
A neural network receives height and weight and predicts whether each resident is a man, woman, or child. Its SGD optimizer uses a learning rate of 0.02; successive epochs reduce the loss, with most training examples classified correctly after the first epoch. section 9.2.3
Equation 8.15
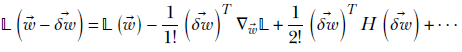
Equation 8.15 connects the learning rate to the local gradient-descent step and the direction producing the largest decrease. section 8.4.3















