The learning rate is a hyperparameter that sets the step size for updating model parameters during gradient descent. It is chosen before training, unlike learned weights and biases. section 8.1 section 8.1.1
Each update moves parameters opposite the loss gradient and scales that movement by the learning rate. A value that is too high can overshoot the minimum; a value that is too low can slow training or become stuck in a local minimum. section 8.1.1
Figure 8.1 Gradient descent with lr = 0.1, demonstrating faster convergence
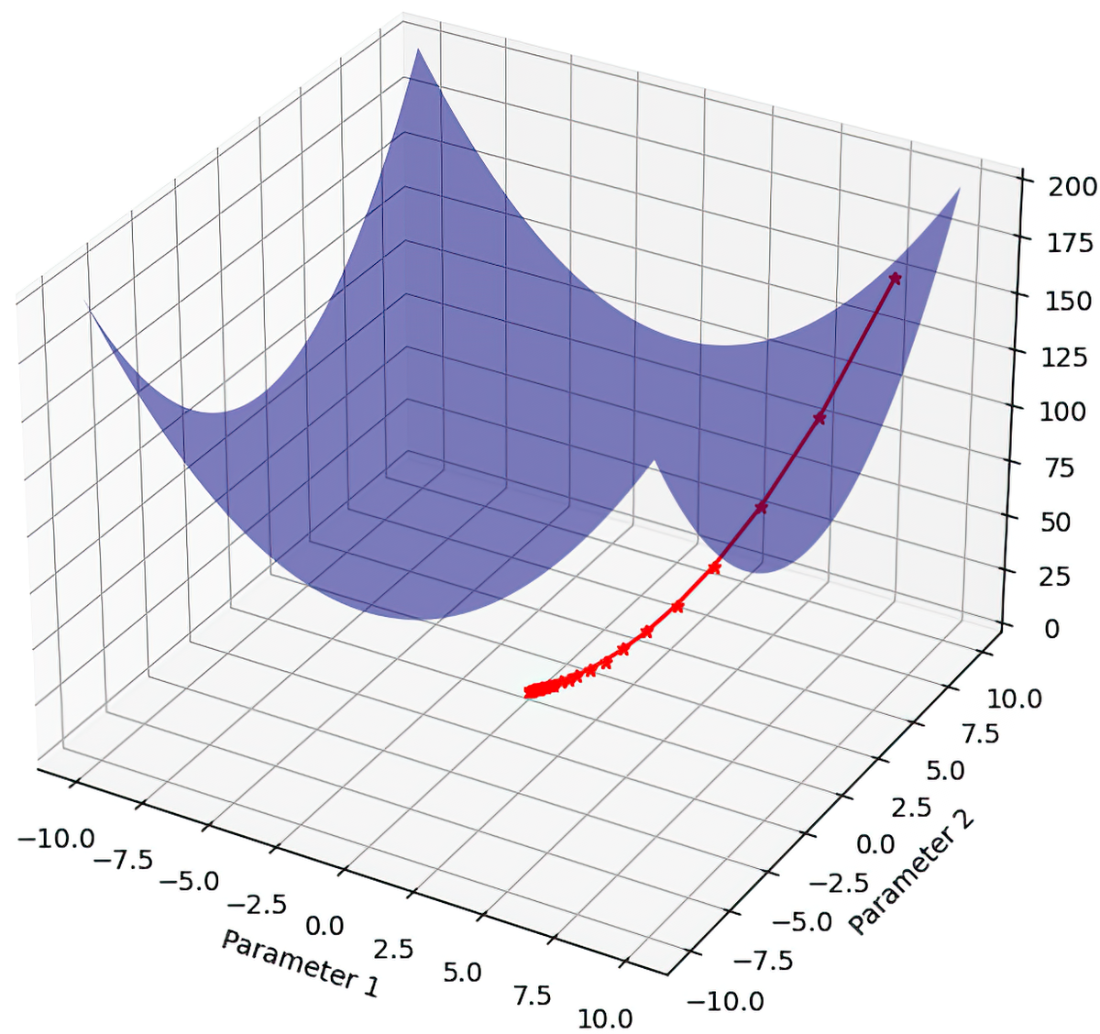
Compare gradient descent with a learning rate of 0.1, which emphasizes faster convergence, against 0.01, which emphasizes stability. section 8.1.1
Configuring learning rate for translation fine-tuning
A supervised fine-tuning configuration assigns learning_rate=lr alongside a linear scheduler and a 0.03 warmup ratio. The setup combines a modest rate with gradient accumulation and a limited batch size for constrained VRAM, then evaluates translation behavior after two epochs. section 7.5















