If a spam filter marks an email as spam, how often is it right? Precision answers that question. It measures the proportion of predicted positives that really are positive. For a spam filter, a false positive is an ordinary email incorrectly marked as spam, so precision matters when that mistake is costly. section 7.2 section 7.4
Precision = TP / (TP + FP). A true positive (TP) is correctly predicted as positive; a false positive (FP) is incorrectly predicted as positive. The denominator counts everything predicted positive, not every example in the dataset. You can find both counts in a confusion matrix. section 7.2 section 13.4
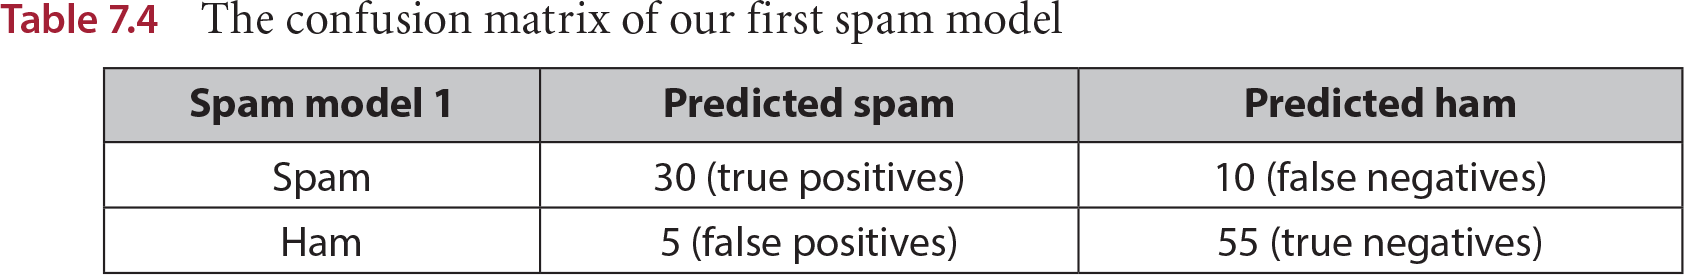
Table 7.4 The confusion matrix of our first spam model (view table figure)
| Spam model 1 |
Predicted spam |
Predicted ham |
| Spam |
30 (true positives) |
10 (false negatives) |
| Ham |
5 (false positives) |
55 (true negatives) |
In this spam-filter confusion matrix, look down the predicted-spam column: 30 emails are true positives and 5 are false positives. section 7.2
Compare two spam filters
The first filter’s precision is 30 / (30 + 5), or about 86%. A second filter catches more spam—35 rather than 30 emails—but also flags 10 ordinary emails rather than 5. Its precision is 35 / (35 + 10), or about 78%. Catching more positives does not necessarily make positive predictions more trustworthy. section 7.2
Precision differs from recall: precision asks whether predicted positives are correct, while recall asks how many actual positives were found. Recall falls with false negatives; precision falls with false positives. Accuracy counts overall correct predictions and can hide important errors when the classes are unbalanced. An F1-score combines precision and recall. section 7.0 section 7.4
Try it with a recommendation system: decide what counts as a positive recommendation, count its true and false positives, and calculate precision. Then ask whether false positives or false negatives would be worse for its user before choosing which metric to emphasize. section 7.5