An evaluation dataset is held-out data used to check how well a model generalizes while it is being developed. The model does not train on it, so its results are more meaningful than scores from the training data. section 11.34 section 8.12
Use the evaluation set as a practical feedback loop:
- Set aside part of the available data before training; an illustrative split uses 80% for training and 20% for testing. section 8.10 section 8.12
- Periodically run the developing model on held-out examples and calculate its loss or another performance measure. section 11.34 section 8.18
- Compare training and evaluation trends: falling training loss alongside rising validation loss signals overfitting. section 11.34
- Stop training when validation loss no longer improves; patience specifies how many unimproved evaluation cycles to wait. section 11.34
Diamonds: checking predictions
For a regression model, compare predicted diamond prices with actual prices from held-out carat examples and measure the difference, such as with R². For a decision tree, feed ten new diamond records through the tree: seven correct classifications give 70% accuracy, while the errors can be summarized with a confusion matrix. section 8.12 section 8.18
Figure 8.14 A regression line plotted with the data points
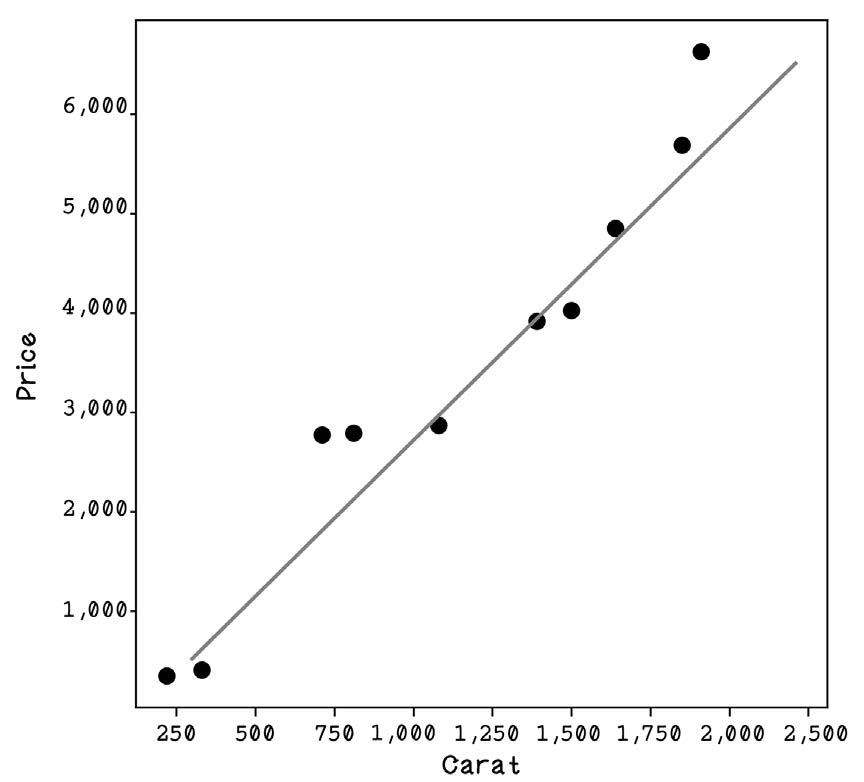
Plot held-out data points against the trained regression line to make prediction accuracy visible. section 8.12


























