An evaluation dataset is held-out data used to assess or tune a model during development. A practical workflow organizes labeled data into training, validation, and test datasets so model changes can be compared without judging them only on training examples. section 1.1.1
For formal evaluation, keep a separate holdout dataset that reflects production diversity, distribution, and characteristics while preventing leakage. Automate evaluation to make results repeatable, then preserve the dataset’s lineage, version, and tracking information as it evolves. section 2.1.4
Use the dataset as part of an iterative model-development loop:
- Prepare and label domain data before organizing it into training, validation, and test datasets. section 1.1.1
- Compare model behavior on held-out data using metrics suited to the problem and its operational goals. section 2.1.4
- Inspect misclassified samples, systemic errors, bias, sensitivity, robustness, and edge cases; feed findings back into data collection. section 2.1.4
- Version data and record evaluation results so a changed split triggers reevaluation and retraining rather than an invalid comparison. section 1.1.1 section 2.1.4
OCR and fraud detection
An OCR system can label images with bounding boxes around ID numbers before dividing them into training, validation, and test datasets. A fraud system may combine customer complaints, expert review, and synthetic data before evaluating errors against a carefully maintained holdout set. section 1.1.1 section 2.1.4
Figure 1.1 The experimentation phase of the ML life cycle
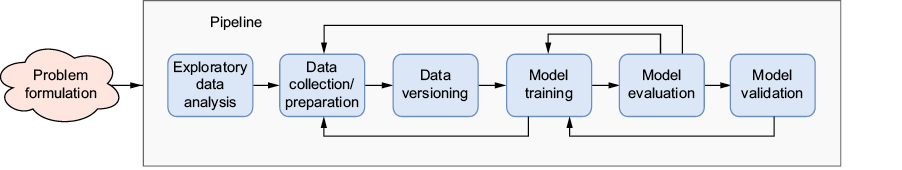
Use the experimentation-phase diagram to place validation data alongside training, evaluation, automation, and tracked model artifacts. section 1.1.1


























