A validation set is a portion of the training data held aside during model development. It evaluates partial models while training and helps identify when continued fitting begins to overfit. section 5.3.1
Use the validation set as part of an early-stopping workflow:
- Reserve a fraction of the training data for validation. section 5.3.1
- Evaluate the partial model on that data after each training iteration and record its metric. section 5.3.1
- Track patience—the number of iterations since the last improvement—and stop when the metric fails to improve for the configured interval. section 5.3.1 section 5.4.4
- Reserve the validation data separately from the test data when using a train/test split, reducing the data available for fitting. section 5.4.4
Gradient boosting
A GradientBoostingClassifier can reserve 20% of its training data with validation_fraction=0.2 and stop after 10 iterations without improvement using n_iter_no_change=10. XGBoost instead receives validation samples and targets through eval_set, monitors eval_metric, and records the best iteration for prediction. section 5.3.1 section 5.4.4
Figure 5.8 A process flow chart describing how early stopping works in GBDTs
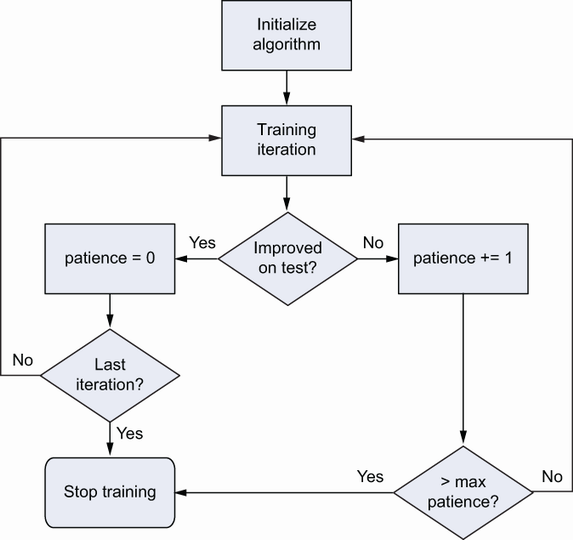
Use the process flow chart to follow validation-based early stopping from data reservation through termination. section 5.3.1


























