An autoencoder learns to reproduce an input: an encoder maps an image to a latent representation, and a decoder reconstructs an output with the original dimensions. Training uses each image as its own target, while low-dimensional or sparse codes encourage compression. Classical autoencoders are useful for understanding latent representations, but their latent spaces are often poorly structured. section 17.1.2
Denoising a degraded image
Feed the model a noisy or low-quality JPEG and ask it to produce a cleaned-up version. Autoencoders can excel at this task, but super-resolution systems may hallucinate details absent from the input, so their output should not be treated as forensic evidence. section 17.2
Keep these practical distinctions in mind:
- Use the encoder to compress an image into fewer bits of information and the decoder to reconstruct it. section 17.1.2
- Treat a variational autoencoder as an extension that encourages continuous, structured latent spaces for generation and controlled image editing. section 17.1.2
- Recognize diffusion models as repeated denoising autoencoders that can transform pure noise into new images. section 17.2
Figure 17.3 An autoencoder: mapping an input x to a compressed representation and then decoding it back as x'
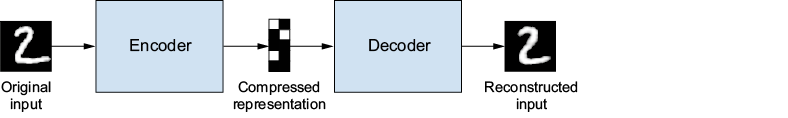
Use the diagram to trace the core path from input image x through a compressed representation to reconstructed image x'. section 17.1.2











