An autoencoder is a neural network that maps an input to a latent representation and decodes it into an output with the original dimensions. It learns reconstruction by using each input image as its own target. Constraining the latent code to be low-dimensional or sparse encourages compression, although classical autoencoders often produce poorly structured representations. section 17.1.2
Figure 17.3 An autoencoder: mapping an input x to a compressed representation and then decoding it back as x’
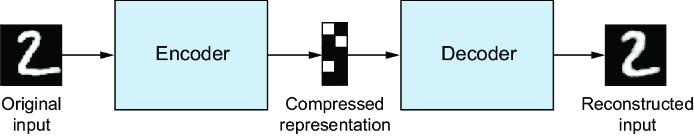
Follow the encoder–latent space–decoder path from input x to reconstructed output x′. section 17.1.2
Autoencoders support several image-processing roles:
- Denoising autoencoders receive a slightly noisy image and reconstruct a cleaned-up version. section 17.2
- Super-resolution models extend denoising to low-resolution images, producing higher-resolution outputs by guessing plausible missing detail. section 17.2
- Variational autoencoders add Bayesian inference and structure the latent representation as a probability distribution, supporting controlled generation and image editing. section 17.1.2
Cleaning a low-quality image
Feed a low-quality JPEG into an autoencoder and train it to produce a cleaner version. The result may look sharper, but super-resolution can hallucinate details absent from the input, so it should not be treated as forensic recovery. section 17.2











