An autoencoder is a neural network that compresses an image into a smaller representation, then reconstructs the image from that representation. The compressed form, called a latent representation, captures patterns such as facial expressions, face angles, and skin tones. section 4.2
Its basic operation has two linked stages:
- An encoder extracts a compressed set of patterns from the original image. section 4.2
- A decoder uses those patterns to reconstruct an image resembling the original. section 4.2
- Using one encoder with separate decoders can map characteristics from one face onto another. section 4.2
Face-swapping
In a deepfake workflow, the same encoder extracts latent features from two faces. A decoder trained for Face B then reconstructs Face A’s features with characteristics such as Face B’s eyes, nose, mouth, and lighting. section 4.2
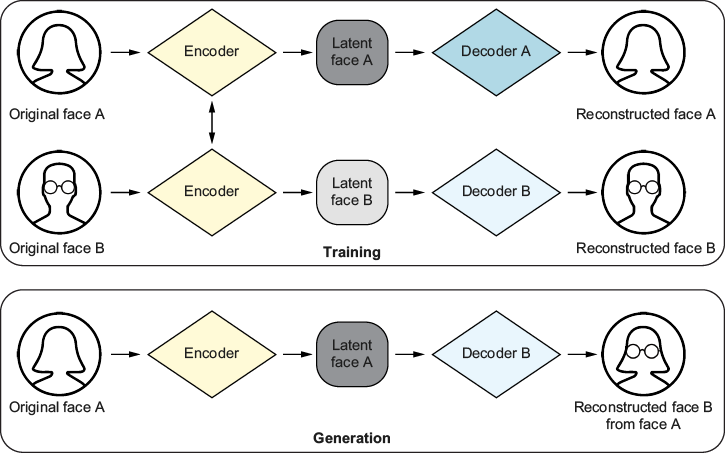
The diagram shows how one encoder produces shared latent features while two decoders reconstruct the faces. section 4.2











