Suppose a pipeline fetches and cleans weather data and sales data before combining them to train a demand-forecasting model. The two branches use separate datasets, so neither needs to wait for the other. A DAG expresses that independence through the absence of dependencies between branches; Airflow can then run ready tasks in parallel rather than executing every step in sequence. section 1.1.3
Figure 1.6 Independence between sales and weather tasks in the graph representation of the data pipeline for the umbrella-demand forecast model. The two sets of fetch/clean tasks are independent because they involve two different data sets (weather and sales). This independence is indicated by the lack of edges between the two sets of tasks.
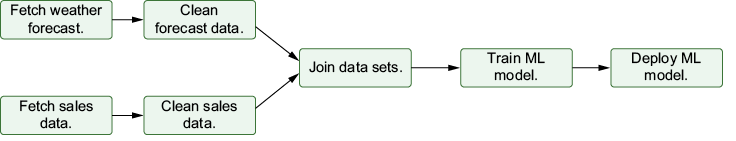
The separate fetch-and-clean branches make the opportunity for parallel execution visible; their downstream work still depends on the required inputs. section 1.1.3
Parallelism is bounded by capacity and configuration, not just by the DAG’s shape. With the default limits shown here, one busy DAG is capped at 16 queued or running tasks even though the global parallelism limit is 32 task instances. Two busy DAGs can together reach that global limit. The default pool has 128 slots, so it does not become the limiting factor in this example. section 15.4.4
Table 15.2 Overview of Airflow configurations related to running number of tasks
| Configuration item |
Default value |
Description |
|
|
|
The maximum number of tasks to be in the queued or running state per DAG |
|
|
|
The maximum number of parallel DAG runs per DAG |
|
|
|
The maximum number of task instances to run in parallel globally |
|
|
|
The maximum number of tasks per Celery worker |
Use the configuration table to distinguish limits on tasks per DAG, concurrent DAG runs, tasks across Airflow, and tasks per Celery worker. section 15.4.4
Increase concurrency according to the bottleneck:
- Adjust max_active_tasks_per_dag and parallelism when their per-DAG and global limits prevent independent tasks from running together. section 15.4.4
- Use pools to restrict groups of costly tasks. Several database queries may be acceptable at once while a handful of CPU-intensive tasks may not be. section 15.4.4
- For CeleryExecutor workers, account for worker concurrency and memory: allow at least 200 MB of RAM per process as a baseline, then consider the worst case when demanding tasks overlap. section 15.4.4
Many tasks waiting on external jobs
If ten workers each hold a task while waiting for an external job, other work must wait for a free worker. Deferrable tasks instead hand that waiting to the triggerer. Using Python asyncio, the triggerer can monitor many external jobs without assigning an idle worker to each one; the deferred processes must support asynchronous operation. This is concurrency for waiting work, not a way to make the triggerer perform those external jobs. section 9.5.1
More parallel tasks can shorten a pipeline and use available resources better, but raising limits without checking worker capacity can create contention. Match DAG dependencies, task limits, pools, and executor capacity to the work being run. section 1.1.3 section 15.4.4





































