A context window is the amount of information an LLM can computationally handle in one request. It is measured in tokens: the prompt, retrieved documents, and often the conversation transcript all compete for the same space. section 5.5.1
A conversation that gets too long
GPT-3 is described as having a 2,048-token context size. Once a chatbot conversation exceeds that limit, the model may lose track of things discussed near the beginning. In retrieval-augmented generation, retrieving an entire book can likewise exceed the window, causing the model to consume only the beginning and miss later information. section 5.5.1 section 5.5.1
Figure 5.11 On the left, we show the normal use of an LLM of a user asking about how to write JSON. LLMs naturally have the chance of producing errant outputs, which we want to minimize. On the right, we show the RAG approach. By using a search engine, we can find documents that are relevant to a query and combine them into a new prompt, giving the LLM more information and context to produce a better answer.
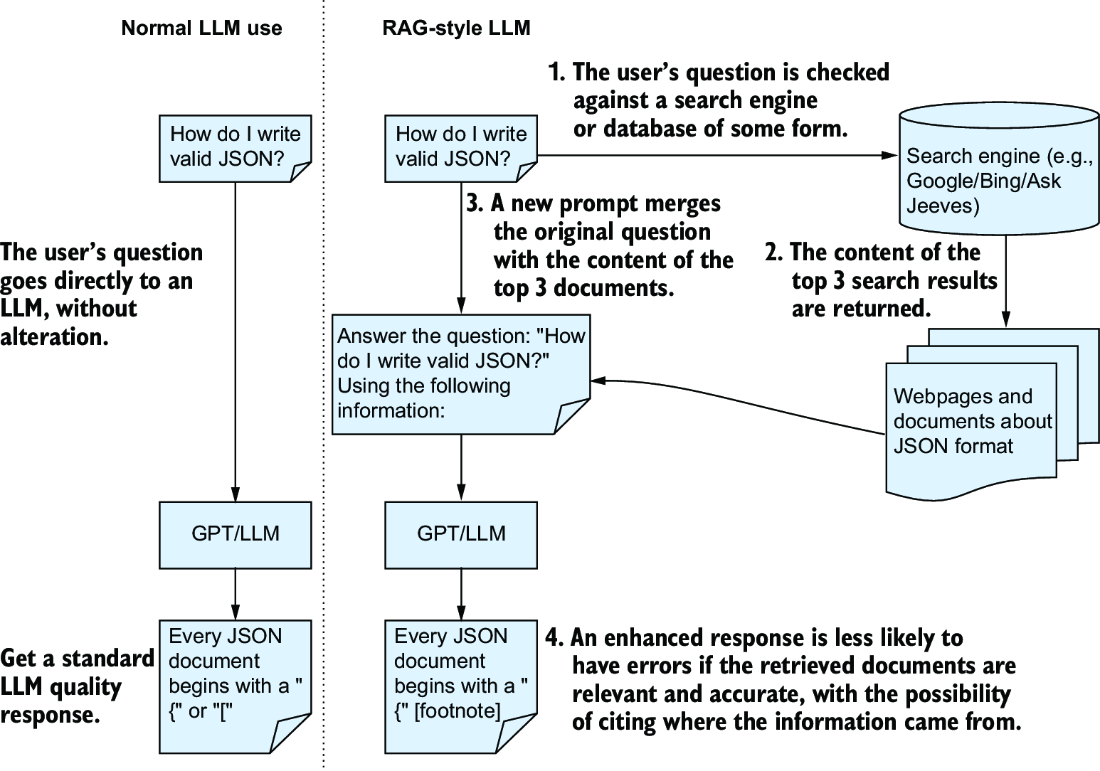
Shows how retrieval adds relevant documents to a new prompt, making context size an operational constraint alongside search quality. section 5.5.1





















