liveBook · Manning

Decoder

As explained in Introduction to Generative AI, Second Edition

A decoder is a model component that reconstructs or generates output data from an intermediate representation.

A decoder reconstructs or generates output from an intermediate representation. In image systems, it turns compressed patterns—such as facial expressions, angles, and skin tones—back into an image. section 4.2

Within an autoencoder, the decoder:

  • Receives latent features produced by an encoder. section 4.2
  • Reconstructs an image from patterns representing the original image’s characteristics. section 4.2
  • Can be trained to map features such as eyes, noses, mouths, and lighting into a different face. section 4.2

Face-swapping

A shared encoder extracts latent features from Face A and Face B. A decoder trained for Face B then reconstructs Face A’s features as a realistic blend resembling Face B. section 4.2
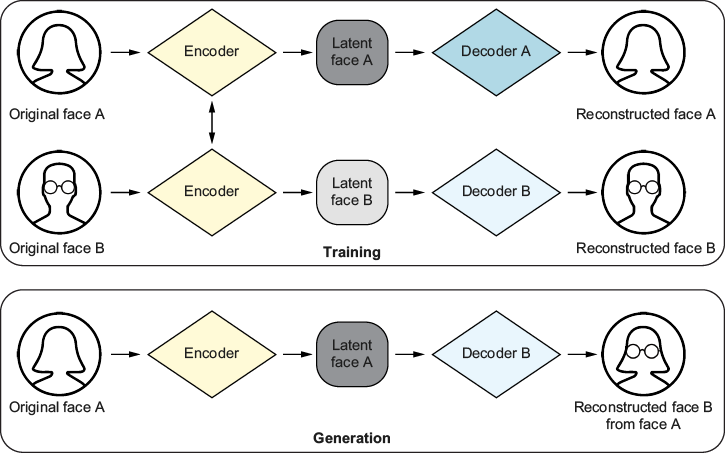
Figure 4.2 Deepfake creation using autoencoders with a single encoder and two decoders

Diagram of deepfake creation using one encoder and two decoders. section 4.2

How Introduction to Generative AI, Second Edition covers it

How deep it goes
Explains the decoder’s role and face-swapping mechanism without implementation details.
Examples
Uses facial features, Face A, Face B, and a single-encoder two-decoder deepfake diagram.
What it assumes
Defines the encoder-decoder relationship and latent representation before explaining image reconstruction.
What you can do after
Understand how decoders transform latent image features into reconstructed or blended faces.
How it connects
Connects decoders to encoders, latent representation, autoencoders, deepfake technology, and face-swapping.

Also explained in

Compare how 5 books explain decoder →

Related concepts

This explainer was generated by Manning's knowledge graph from the text of Introduction to Generative AI, Second Edition. The section links point to the parts of the book it draws on.



