A decoder generates an output sequence from encoded representations and previously generated tokens. In Fusion-in-Decoder, it attends simultaneously to independently encoded question–passage representations and synthesizes an answer. section 5.2
In multi-document processing, the decoder:
- Reads the concatenated encoder representations as one sequence of length N × sequence_length. section 5.2
- Uses cross-attention to access all retrieved passages while generating each answer token. section 5.7
- Enables synthesis across scattered evidence, while making inference latency the main trade-off because attention spans the full concatenated sequence. section 5.7
Question-and-passage decoding
For “Where was T5 developed?”, independently encode question–title–context inputs for retrieved passages, concatenate their representations, and let the decoder generate a synthesized answer. section 5.2
Figure 5.2 The FiD architecture: Independent Encoding, Fused Decoding.
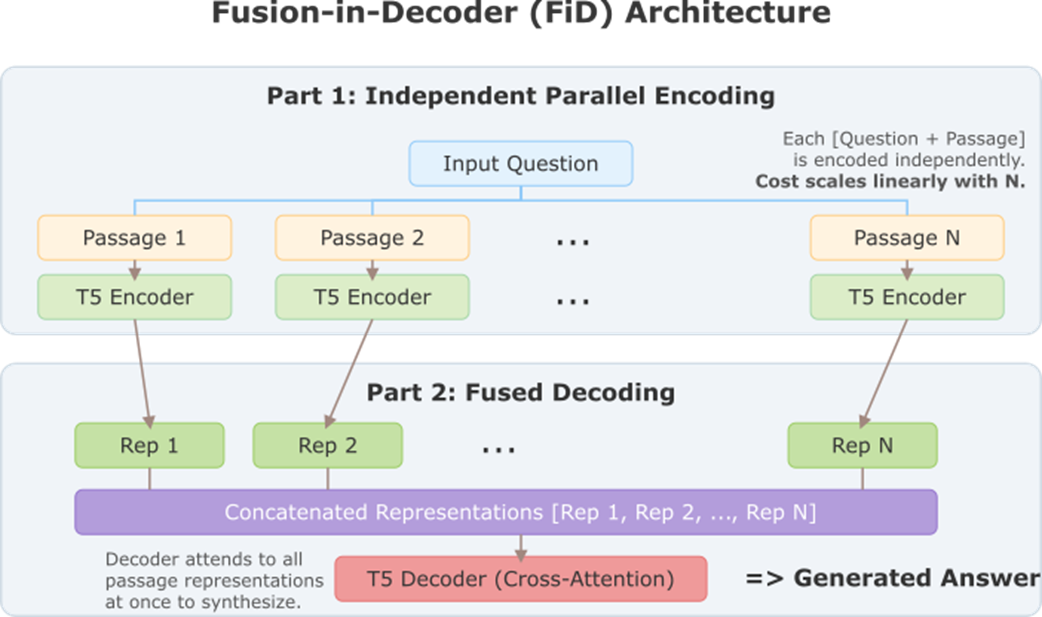
Use the architecture diagram to trace independent encoding, representation fusion, and decoder attention over all passages. section 5.2








