A weather dashboard needs fresh forecast data in a usable form. An ETL pipeline fetches data from a source, transforms it for its intended use, then loads the result into a destination. Fetching, transforming, and loading are separate tasks because each depends on the preceding result. section 1.1
For the dashboard, the task order is:
- Extract forecast data from a weather API. section 1.1
- Transform the data, perhaps converting temperatures between Fahrenheit and Celsius. section 1.1
- Load the transformed data into the dashboard. Loading before transformation would publish data that is not yet ready. section 1.1
Airflow coordinates these tasks rather than performing every data operation itself. A Python-defined directed acyclic graph (DAG) records task dependencies so the scheduler can run the pipeline in the required order. Its interface supports monitoring, debugging, and rerunning tasks; scheduling and failure handling make the approach useful for recurring batch jobs. section 1.0 section 1.5
A periodic analytical export
A daily ETL job can export data from a production database for transformation and storage elsewhere. Keeping periodic exports can preserve historical data that the production database cannot return later. Plan for the resulting storage growth: processing accumulated dumps may require distributed processing. section 8.3
Before building a recurring pipeline, inspect a sample of the source data. Check its format, size, arrival frequency, and whether it must be processed again. An hourly Wikimedia page-views dump, for example, can be inspected for unexpected characters or shifted columns before deciding whether cleaning is needed and how to load subsequent dumps incrementally. section 5.1
Moving data across several systems
A transportation analysis extracts Citi Bike data from a REST API and Yellow Cab data from a file share, then transforms the data for results stored in PostgreSQL and displayed on a web page. MinIO provides S3-compatible object storage among the services. This illustrates why source access, intermediate storage, transformation, and the final destination must be coordinated. section 13.1
Figure 13.1 Our Docker Compose file creates several services. Our task is to load data from the REST API and file share and then transform it so we can eventually view the fastest method of transportation on the resulting web page.
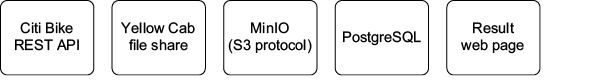
The service diagram shows the REST API and file share feeding a pipeline whose transformed results can be viewed on a web page. section 13.1


















