Feedback is human judgment about a system’s behavior or output. In reinforcement learning from human feedback (RLHF), people compare generated responses and prefer the one they like more, teaching the model what humans consider acceptable rather than simply what completes a task. section 5.3.3
Treat feedback as useful but imperfect production data:
- It can improve human acceptability and support continual model updates. section 5.3.3
- It is expensive because evaluation may require domain experts and substantial computation. section 5.3.3
- It can expose private traffic and encode reviewer or user bias, so preference is not the same as factual correctness. section 5.3.3
- Continual feedback updates can also degrade performance over time. section 5.3.3
Comparing generated answers
Given a prompt, a human reviews multiple generated responses and selects the preferred answer. The preference can reward concise, acceptable behavior even when it does not improve factual accuracy. section 5.3.3
Figure 5.6 RLHF substitutes a loss function for a reward model and proximal policy optimization (PPO), allowing the model a much higher ceiling for learning trends within the data, including what is preferred as an output instead of what completes the task.
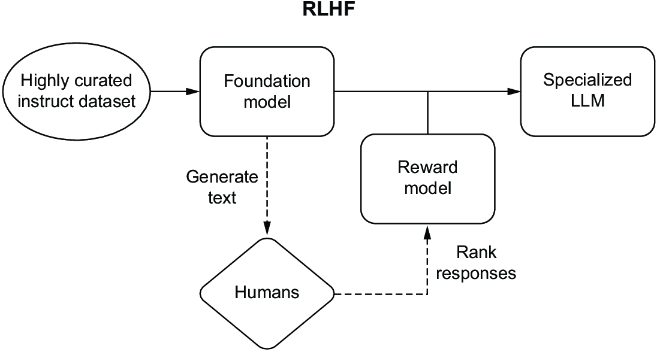
Trace how RLHF replaces a direct loss signal with a reward model and PPO to learn preferred outputs. section 5.3.3