A logit is an unnormalized real-valued score assigned to a possible output token. The transformer produces these scores after contextual representations pass through the feed-forward network, remaining transformer blocks, final layer normalization, and an output projection. section 2.2.2
During next-token prediction, logits support a compact selection pipeline:
- Select the last row of the logits matrix, because it represents predictions after the complete input context. section 2.2.3
- Treat that row as one score for every vocabulary token; for the example input, the vector has shape (1, 50257). section 2.2.3
- Apply softmax to convert the scores into probabilities, then use argmax to select the most likely token. section 2.2.3
- Modify the final logits with temperature scaling, top-k, or top-p sampling to control generation before selection. section 2.2.3
Predicting after “The next day is”
The model may produce a logits matrix with shape (4, 50257), containing predictions for every input position. Only the final row is relevant: after conversion to probabilities, the highest-scoring token could be “bright.” section 2.2.3
Figure 2.12 The journey from the final context matrix to the logits matrix. The output layer projects each context-aware vector into a long vector of scores, one for each word in the vocabulary.
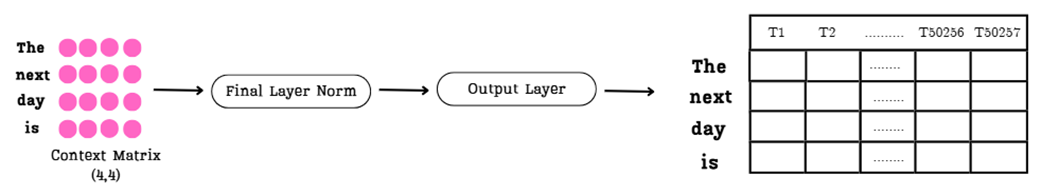
Trace how the final context matrix becomes a vocabulary-sized logits matrix through the output projection. section 2.2.2























