Drift occurs when a deployed model’s operating conditions change while its assumptions stay fixed. Data drift is a shift in the distribution of incoming inputs relative to the data used for training. In a solar-power forecast, dirt accumulating on panels, growing tree shadows, and aging photovoltaic cells can make data from 2026 unlike the data used to train the model in 2025. section 10.3.2
The source of a change matters:
- Data drift: incoming values acquire different statistical properties, as solar production values may do over time. section 10.3.2
- Concept drift: the relationship between variables changes; replacing a gas cooktop with an induction cooktop changes how time of day relates to electricity use. section 10.3.2
- Sensor drift: the measurement device changes; a temperature sensor may gradually lose calibration. section 10.3.2
Figure 10.3 Data drift in solar production data, where the distribution of current values (on the right) has drifted from a reference data set (on the left)
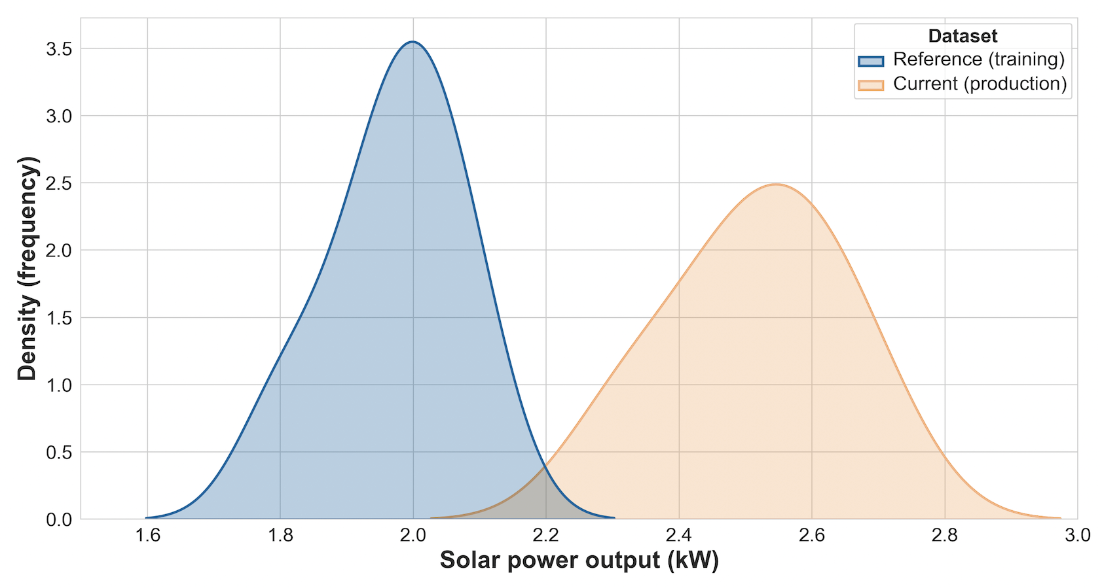
Compare the reference and current solar-production distributions. The change concerns the pattern of values, not just one unusual reading. section 10.3.2
Listing 10.3 Using Evidently to track drift in live telemetry data against a known state
import pandas as pd
from evidently import Report
from evidently.presets import DataDriftPreset

reference = pd.DataFrame({  #1
    "power_kw": [1.8, 2.0, 1.9, 2.1, 2.0, 1.95, 2.05]
})

current = pd.DataFrame({  #2
    "power_kw": [2.4, 2.5, 2.6, 2.3, 2.7, 2.5, 2.6]
})

report = Report([DataDriftPreset()])

result = report.run(current, reference)

result.save_html("power_drift_report.html")

print(result.json())
The Python example creates reference and current power-data frames, runs Evidently’s DataDriftPreset, and saves an HTML report. The same comparison can be extended to multidimensional sensor streams and continuous monitoring. section 10.3.2
A detected change is a prompt for investigation, not an automatic fault verdict. An operator can decide whether a 20% increase in average daily energy use signals a problem or a new normal; a confirmed new normal can be labeled and used to trigger retraining. Production monitoring also needs performance baselines, versioned feature pipelines, training-data provenance, and defined retraining triggers so changes can be traced and acted on. section 10.3.2 section 8.5.3











