Normalization rescales numerical search features to comparable ranges so one feature does not dominate a ranking model merely because its raw values are larger. SVM-based learning to rank is especially sensitive to feature ranges. section 10.4.1
A standard normalization maps the feature mean to 0 and one standard deviation above or below the mean to +1 or -1. For example, with a mean release year of 1990 and standard deviation of 22, 2012 becomes 1.0 and 1968 becomes -1.0. Apply the same calculation to title_bm25, overview_bm25, and other ranking features using statistics from the training data. section 10.4.1 section 10.4.2
Normalizing movie-ranking features
A logged judgment might contain title_bm25 8.244, overview_bm25 3.814, and release_year 2010. After normalization, these values become comparable standard-deviation-based features; the normalized dataset preserves the relationships while changing the axis scales. SVMrank can then compare relevant and irrelevant documents without bias from unusually large feature ranges. section 10.4.2
Normalization belongs both in training and deployment. Store each feature's mean and standard deviation with the linear ranking model, normalize evaluated documents with those statistics, and apply the model during search. In production, use learning to rank as a second-stage reranker: an initial BM25 or Boolean query narrows the candidates, then the more expensive model reranks the top results. section 10.6.1
Figure 10.5 Separating hyperplane affected by the range of one of the features. This causes SVMs to be sensitive to the range of features, and thus we need to normalize the features so one feature doesn’t create undue influence on the model.
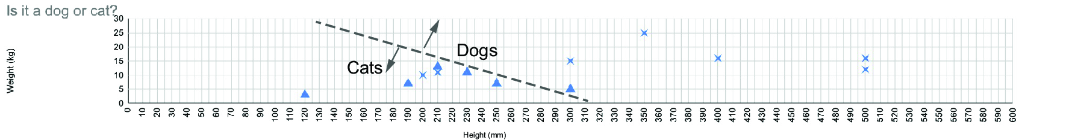
Shows how changing one feature's range changes the separating hyperplane, motivating comparable feature scales. section 10.4.1




















