Reinforcement learning from human feedback improves a language model by having people judge its responses. The model uses those judgments as a feedback loop, learning through trial and error to produce more effective, human-like conversation. section 1.5
A conversational model develops through three broad stages:
- Unsupervised learning teaches the model to predict coherent word completions. section 1.5
- Supervised refinement trains it on human conversation examples for meaningful question-and-answer exchanges. section 1.5
- Human reviewers identify effective and ineffective responses, guiding later behavior toward better conversations. section 1.5
Figure 1.6 The learning stages of ChatGPT
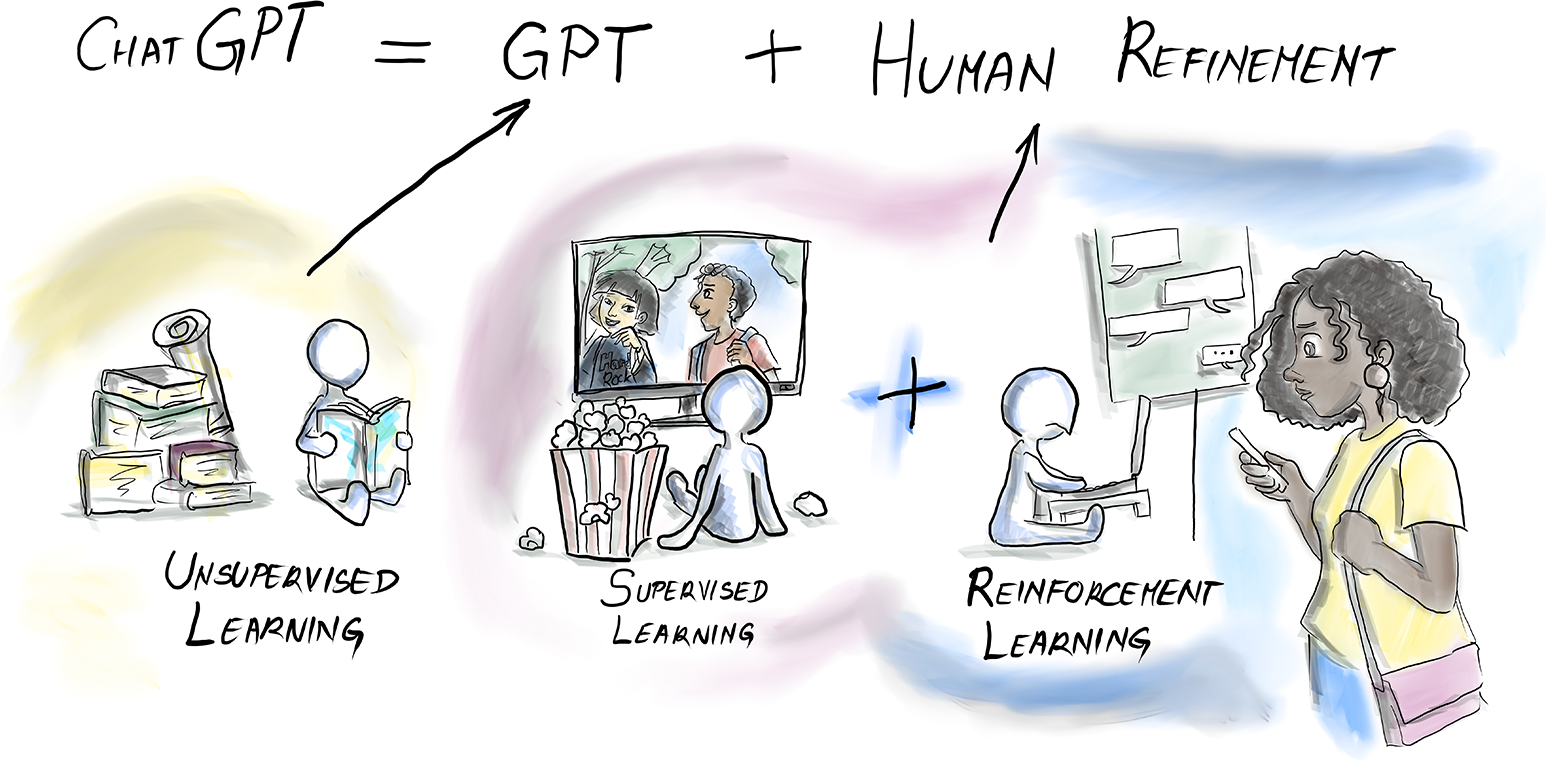
The learning-stages figure provides a visual overview of how human feedback follows unsupervised learning and supervised refinement. section 1.5













