Reinforcement learning from human feedback (RLHF) adapts a model to preferences that are difficult to write as a programmatic objective. For language models, it chiefly turns a pretrained text completer into a more useful instruction-following assistant, shaping response style, tone, format, and quality. The preference signal is indirect: people express which outputs they prefer, and training converts those judgments into an optimization target. section 1.0 section 1.2 section 1.7
The canonical recipe has three stages. First, supervised instruction fine-tuning teaches question-and-answer behavior from high-quality demonstrations. Next, a reward model is trained on preference relations between candidate responses, learning to assign a scalar score to a prompt and completion. Finally, the instruction-tuned policy generates fresh completions and is updated with reinforcement learning to obtain higher reward. section 1.3 section 3.2.1
Figure 1.1 A rendition of the early three-stage RLHF process: training via supervised fine-tuning (SFT; chapter 4), building a reward model (RM, chapter 5), and then optimizing with RL (chapter 6).
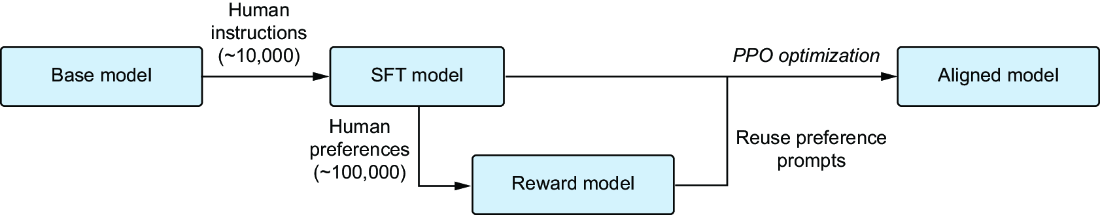
The three-stage diagram shows the dependency chain: supervised fine-tuning supplies the starting policy, preference data trains the reward model, and RL optimizes the policy against that model. section 1.1
In the usual language-model formulation, a prompt is sampled from a dataset and the model’s full completion is the action. A learned reward model replaces an environment reward function; rewards are generally assigned to the whole response rather than individual tokens. Because a completion normally does not create the next prompt, the setup is often single-step and uses no discounting. Optimization also penalizes divergence from a frozen reference policy with KL divergence, limiting excessive drift from the instruction-tuned model. section 3.1.3 section 3.3
From completion to answer
Given “The president of the United States in 2006 was,” a base model may continue with a sprawling mixture of related facts and web-like metadata. A post-trained model instead gives a concise answer identifying George W. Bush and his term dates. This contrast illustrates how post-training changes the presentation of knowledge, not merely next-token continuation. section 1.2
The RL stage closes the preference-learning loop:
- Sample prompts and generate completions with the current policy. section 6.0
- Score each completion with the reward model and combine that signal with the KL penalty. section 6.0
- Apply policy-gradient updates; PPO, REINFORCE-style methods, and GRPO represent different trade-offs in memory, value estimation, and stability. section 6.1 section 6.6
RLHF is one part of post-training, alongside instruction fine-tuning and reinforcement learning with verifiable rewards. Preference fine-tuning is especially useful for subtle human judgments, but its reward model is a proxy trained on noisy data. Over-optimizing that proxy can produce undesirable behavior such as excessive length or chattiness and can harm performance elsewhere. Direct alignment algorithms offer a related route: they optimize a policy directly from pairwise preference data rather than first training an intermediate reward model. section 1.1 section 1.7 section 3.1.5













