Reinforcement learning with human feedback (RLHF) fine-tunes model behavior from human usage and feedback, increasing the probability of outputs that fit observed patterns. The technique helps explain why outputs vary, because LLMs remain probabilistic rather than repositories of structured information. section 2.1
Predictive messaging analogy
A phone keyboard may increase the probability of words such as “I am” and “away” because someone types them frequently. This illustrates RLHF, although applying the analogy directly to LLMs is an oversimplification. section 2.1
Figure 2.1 Probability distribution in action
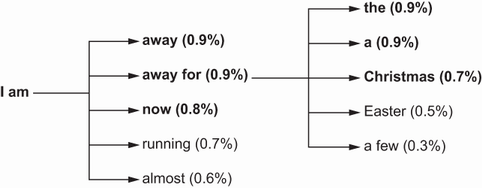
Use the probability-distribution figure to visualize why model outputs are probabilistic and require vigilance. section 2.1













