Uncertainty describes how unpredictable or mixed the classes in a dataset are. A group containing one class is more settled than a group mixing several classes. Decision-tree training uses this measure to choose questions that make the resulting groups clearer. section 8.17
Choosing a clearer split
Suppose a diamond dataset labels examples as Okay or Perfect. The tree tests questions such as “Is Carat >= 0.5?” or “Is Price >= 3,045?” It counts labels, measures the current uncertainty, splits the examples, measures the uncertainty remaining in both groups, and selects the question with the greatest information gain. section 8.17
The implementation makes the calculation concrete:
- Counts how many examples belong to each label. section 8.17
- Uses class probabilities to calculate Gini uncertainty. section 8.17
- Subtracts weighted post-split uncertainty from the current value to obtain information gain. section 8.17
Figure 8.20 Example of uncertainty
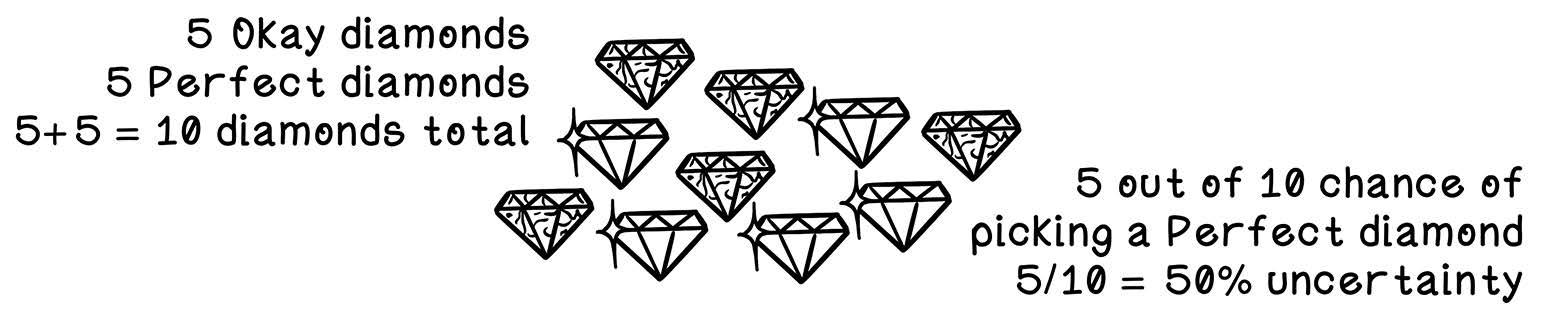
Use the uncertainty illustration to reinforce the contrast between mixed and settled class groupings. section 8.17









