Version control records and retrieves distinct training-dataset versions so data collection can evolve separately from data consumption while model development remains reproducible. section 2.1.1
In a multi-team deep learning system, version control helps by:
- Separating training-data collection from preprocessing, training, and evaluation through managed dataset versions. section 2.1.1
- Preserving the dataset state associated with model development, making results easier to reproduce. section 2.1.1
- Supporting strongly typed data schemas that provide handshakes between teams working on different workflow stages. section 2.1.1
Figure 2.4 A dataset management component creates a good separation between training data collection and consumption by defining strongly typed schemas for both, which allows data development and model algorithm development to iterate in their own loop, thus expediting the project development.
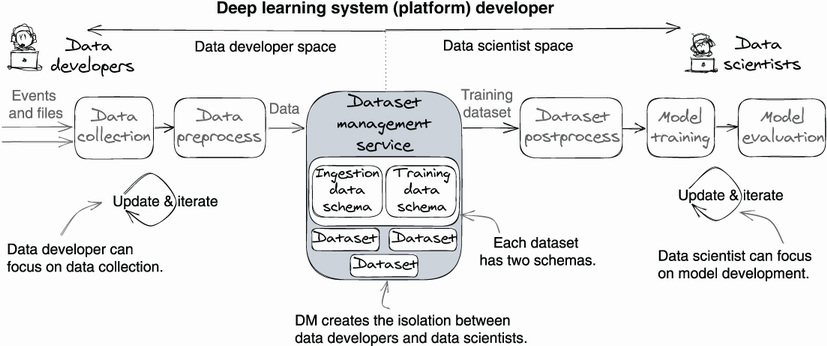
Use the reference architecture to see how dataset management separates data development from model algorithm development through strongly typed schemas. section 2.1.1