A dataset is a structured collection of representative examples used to evaluate whether an agent behaves correctly. For agents that modify schedules, create tickets, or send messages, evaluation must consider both the response and the consequences of tool actions. section 10.2
Evaluation datasets commonly come from three sources:
- Benchmarks provide standardized public sets for baseline comparisons, but controlled tasks may diverge from real product use. section 10.2.2
- Custom datasets contain internally designed scenarios reflecting product tasks, including multiple difficulty levels, domains, and edge cases. section 10.2.2
- Production datasets use real user interactions and feedback collected after deployment, making evaluation realistic but often lacking ground-truth labels. section 10.2.2
A practical evaluation workflow starts with representative user requests, runs the agent on them, and collects complete execution traces: tool calls, available reasoning steps, outputs, and errors. Reviewing these traces reveals recurring failures before scoring begins. Similar failures form a taxonomy, whose frequency and severity inform a rubric and measurable evaluation metrics. section 10.2
Starting a custom dataset
Begin with a small core set—sometimes only a few dozen examples—covering common product scenarios. Expand it over time with harder cases, additional domains, and edge cases revealed by trace review and deployment. section 10.2.2
Figure 10.2 Workflow for defining agent evaluation criteria, from open coding to defining metrics
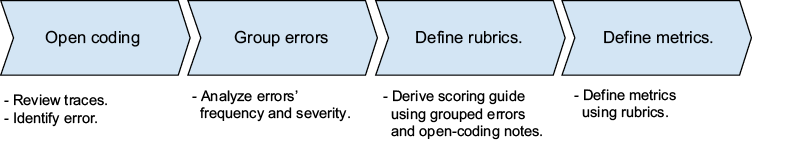
Use the workflow diagram to follow the path from representative requests and open-ended trace review to failure taxonomies, rubrics, and metrics. section 10.2
Table 10.2 Types of evaluation datasets
| Type |
Description |
Pros |
Cons |
|---|---|---|---|
| Benchmark |
Standardized public evaluation sets (e.g., HotpotQA, GAIA, and SWE-bench) |
Comparable across systems; validated difficulty and quality |
May diverge from real use; risk of overfitting to the benchmark |
| Custom |
Internally constructed evaluation sets designed to reflect real scenarios |
Tailored to product needs; domain-specific evaluation |
High build cost |
| Production |
Real user requests and feedback collected in production |
Most realistic evaluation; reflects real use patterns |
Often lacks ground-truth labels |
Use the comparison table to distinguish benchmark, custom, and production datasets by purpose, strengths, and limitations. section 10.2.2























