A dataset is a collection of training examples that helps a model improve its predictions. Like a student checking guesses against new information, a neural network repeatedly uses examples to reduce errors. section 1.6
Useful dataset design follows a simple pattern:
- Gather varied material so the model encounters many subjects, disciplines, contexts, and topics. section 1.6
- Present examples during repeated training passes, allowing the network to adjust its parameters when predictions are wrong. section 1.6
GPT-3 training data
GPT-3 used a 45 TB dataset containing scraped webpages, books, English Wikipedia, and academic articles. This broad collection supported text completion across varied contexts. section 1.6
Figure 1.12 The two stages of GPT-3. First, it gets trained, and then the sentence completion is inferred.
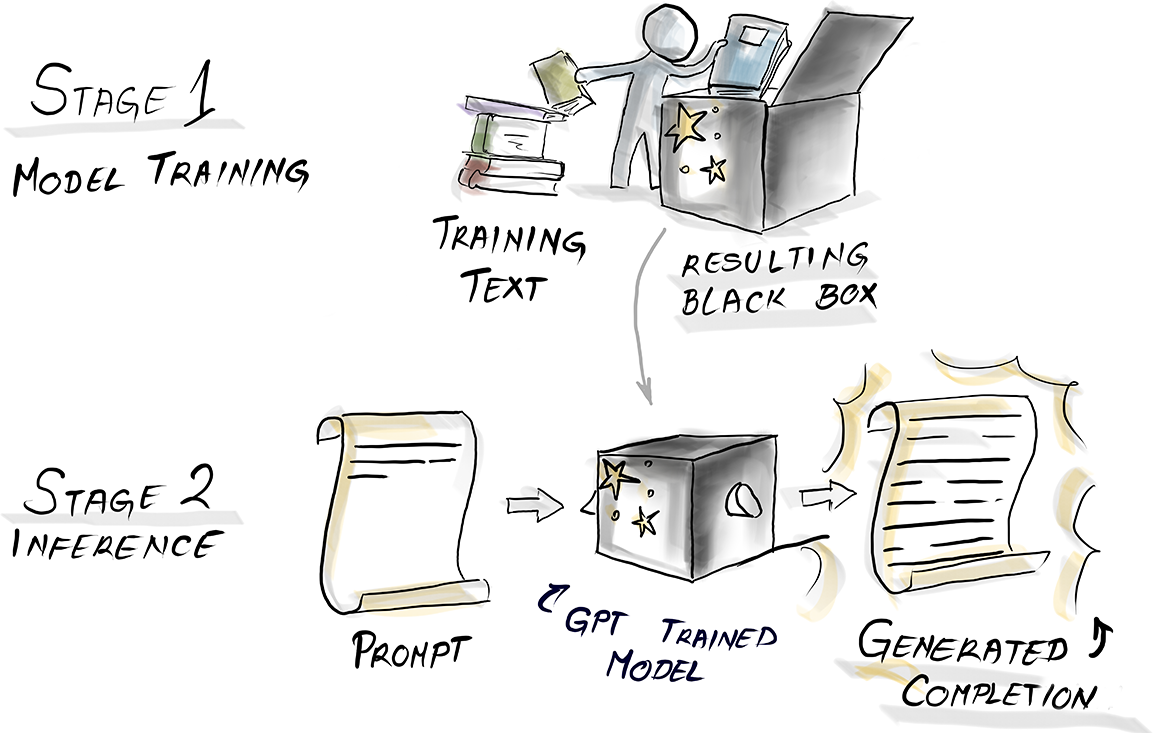
Visualizes the distinction between training a model and inferring a sentence completion. section 1.6























