A dataset is a collection of data instances available for analysis or machine learning. In an ML delivery project, it becomes usable when teams clean and assemble the data into model-ready examples, then deliver it through versioned, tested pipelines. section 5.0 section 1.1
Treat dataset work as a delivery and governance task:
- Open the data with the project infrastructure, establish access, and build pipelines that deliver a dataset to the team. section 5.0
- Add data tests so pipeline failures become visible before unreliable data reaches models. section 5.0
- Treat combined datasets cautiously: population-specific and observational data can introduce bias, while different collection periods may hide important differences. section 5.4.1
Combining data sources
A controlled study may use a test-negative protocol to select comparable control and target groups. Combining that high-quality dataset with general observational data can create a broader model while introducing bias through different selection factors. section 5.4.1
Figure 1.1 The kind of system that ML projects attempt to deliver
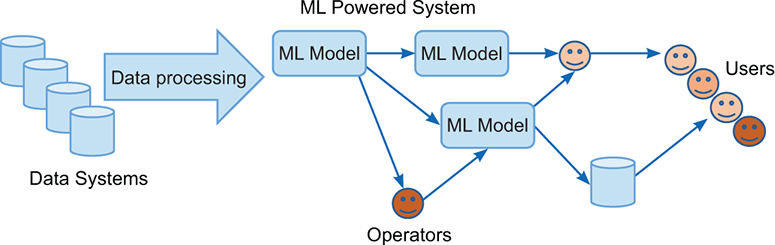
Trace how a dataset becomes processed model input, supports chained models, and reaches users through operators, human review, or another system. section 1.1























