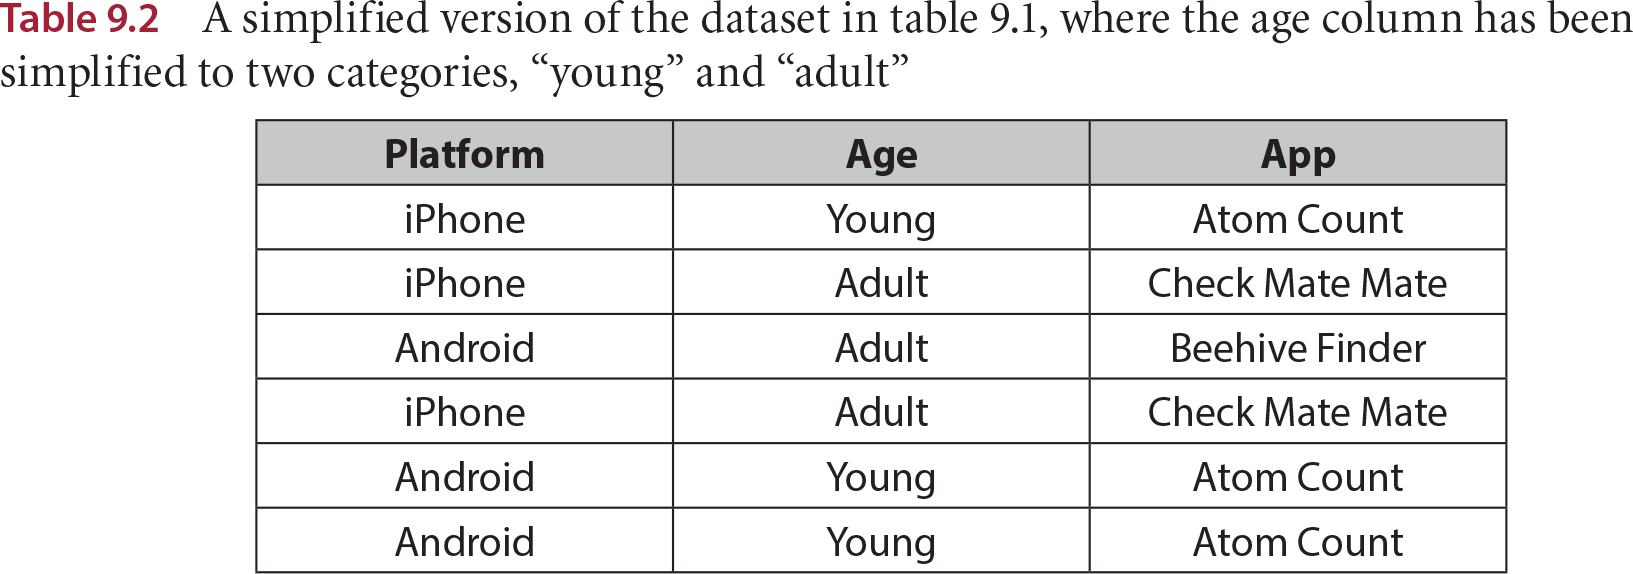
A dataset is a collection of records organized around data points and their features. In an app-recommendation example, each record pairs a user's platform and age with the app they downloaded. section 9.2
Table 9.2 A simplified version of the dataset in table 9.1, where the age column has been simplified to two categories, “young” and “adult” (view table figure)
| Platform |
Age |
App |
| iPhone |
Young |
Atom Count |
| iPhone |
Adult |
Check Mate Mate |
| Android |
Adult |
Beehive Finder |
| iPhone |
Adult |
Check Mate Mate |
| Android |
Young |
Atom Count |
| Android |
Young |
Atom Count |
The table shows six user records, each with platform, age category, and downloaded app. section 9.2
A decision tree splits a dataset into smaller groups using questions about its features. Datasets also need practical preparation: handle missing values, encode categories when needed, select useful features, and divide the data for training, validation, and testing. section 9.2 section 13.7