A GPT model is a decoder-only Transformer that turns token sequences into next-token predictions, enabling text or music generation. It can be built from scratch for a focused dataset and task. section 12.1 section 14.3
The model embeds tokens and their positions, processes them through stacked decoder blocks, and produces vocabulary-sized logits. Each block combines causal self-attention with a feed-forward network, using layer normalization and residual connections. section 12.1.1 section 12.3.3
A practical GPT training workflow includes:
- Choose sequence length, embedding dimension, decoder-layer count, attention heads, vocabulary size, and dropout rates. section 12.1 section 14.3
- Tokenize raw text, map tokens to integer indexes, divide the sequence into fixed-length inputs, and shift them to create next-token targets. section 12.1 section 12.1.2
- Train on varied text that matches the desired style, then generate by repeatedly selecting a next token from the prompt-conditioned predictions. section 12.1.2 section 12.1
A compact GPT configuration
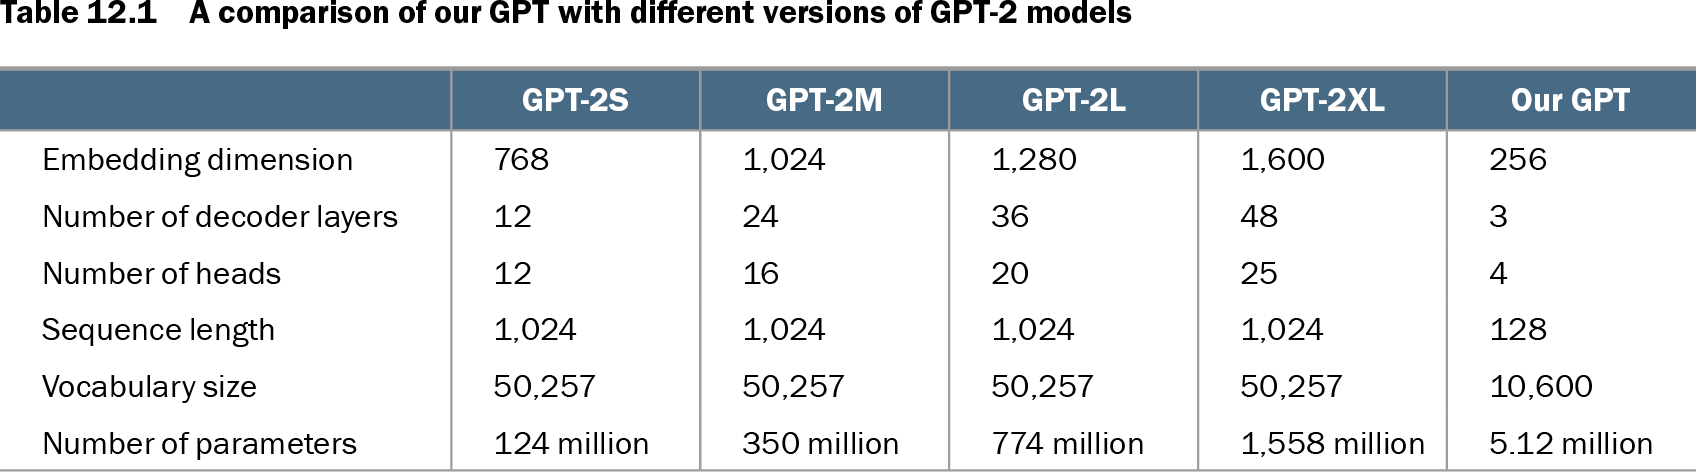
A small implementation uses three decoder layers, 256-dimensional embeddings, four attention heads, a maximum sequence length of 128, and a 10,600-token vocabulary. Word and positional embeddings are added, the result passes through the decoder stack, and a linear head returns 10,600 logits. This configuration contains 5.12 million parameters, making training feasible without supercomputing facilities. section 12.1.1 section 12.3.3
Table 12.1 A comparison of our GPT with different versions of GPT-2 models (view table figure)
| GPT-2S |
GPT-2M |
GPT-2L |
GPT-2XL |
Our GPT |
|
|---|---|---|---|---|---|
| Embedding dimension |
768 |
1,024 |
1,280 |
1,600 |
256 |
| Number of decoder layers |
12 |
24 |
36 |
48 |
3 |
| Number of heads |
12 |
16 |
20 |
25 |
4 |
| Sequence length |
1,024 |
1,024 |
1,024 |
1,024 |
128 |
| Vocabulary size |
50,257 |
50,257 |
50,257 |
50,257 |
10,600 |
| Number of parameters |
124 million |
350 million |
774 million |
1,558 million |
5.12 million |
Compare embedding dimensions, decoder layers, attention heads, sequence lengths, vocabulary sizes, and parameter counts with GPT-2 variants. section 12.1.1