The vanishing gradient problem occurs when gradients become extremely small as they propagate backward through many layers or sequence steps. Learning then slows, and recurrent networks struggle to retain information from far back in a sequence. section 8.7.1 section 8.9.1
The problem appears in several neural-network settings:
- Plain recurrent neural networks can lose long-term dependencies because gradients vanish while information moves across time steps. section 8.7.1
- Deep belief networks can encounter diminishing gradients as errors propagate backward through many layers, complicating fine-tuning. section 8.9.1
- Long short-term memory networks mitigate the problem with input, forget, and output gates that regulate information flow. section 8.7.1
Figure 8.14 The RNN process. RNNs have internal memory, which allows them to use information from the previous inputs to influence the current input and outputs.
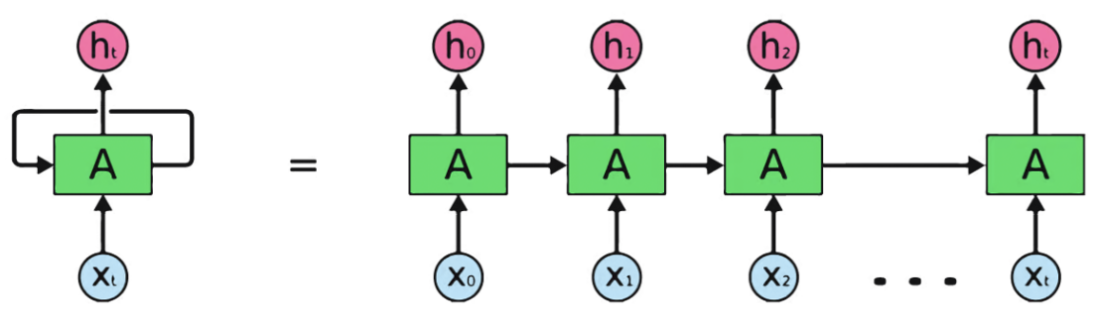
Use the RNN process diagram to trace how hidden-state information passes from previous inputs into current inputs and outputs, clarifying why long sequences challenge information retention. section 8.7.1













