The vanishing gradient problem occurs when derivatives become extremely small, making parameter updates ineffective and causing a network to stop learning. With sigmoid or hyperbolic-tangent activations, inputs near the extremes flatten the curve, so its gradient approaches zero. section 9.10 section 9.2
Common causes and responses include:
- Using sigmoid or hyperbolic tangent at extreme values can produce tiny derivatives; hyperbolic tangent has steeper derivatives but can still vanish at its extremes. section 9.10
- Initializing weights too small can weaken the signal across layers until learning stops, while overly large weights create the contrasting exploding-gradient problem. section 9.14
- ReLU allows some neurons not to activate and can reduce computation, while smart initialization aims to keep activation variance consistent across layers. section 9.10 section 9.14
The Telephone Analogy
Imagine a 100-layer game of Telephone. If each layer passes along a slightly weaker whisper because the weights are too small, the final listener hears nothing. That fading signal represents the vanishing gradient; balanced initialization keeps the signal at roughly the same strength as it travels through the network. section 9.14
Figure 9.29 Common used activation functions
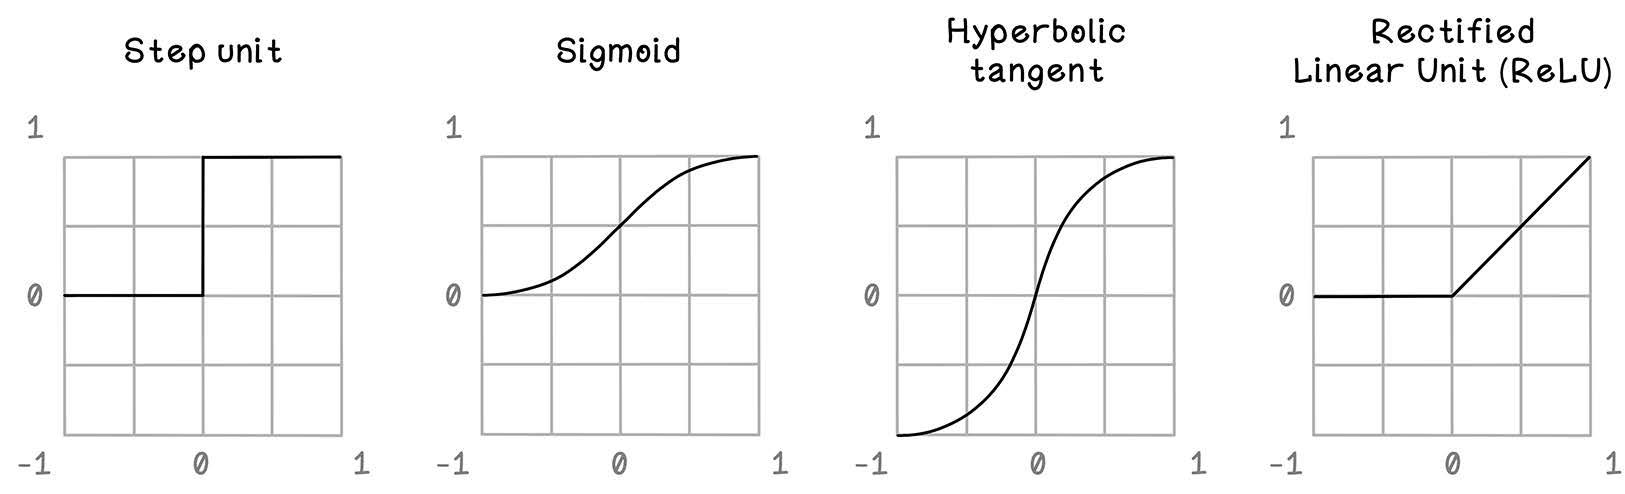
Compare sigmoid, hyperbolic tangent, and ReLU visually to see which activation curves flatten and which permit stronger learning behavior. section 9.10













