Clustering groups data points that are similar, even when their labels are unknown. It can reveal patterns or make data easier to handle. section 2.3 section 2.5
Similarity depends on the data and features being considered:
- Group houses by location, price, size, or a combination of these features. section 2.3
- Group emails by size and number of recipients; a plotted example shows three clusters. section 2.3
- Group unlabeled images by similarity, potentially separating cats from dogs or grouping breeds. section 2.3
Figure 2.5 A plot of the email dataset. The horizontal axis corresponds to the size of the email and the vertical axis to the number of recipients. We can see three well-defined clusters in this dataset.
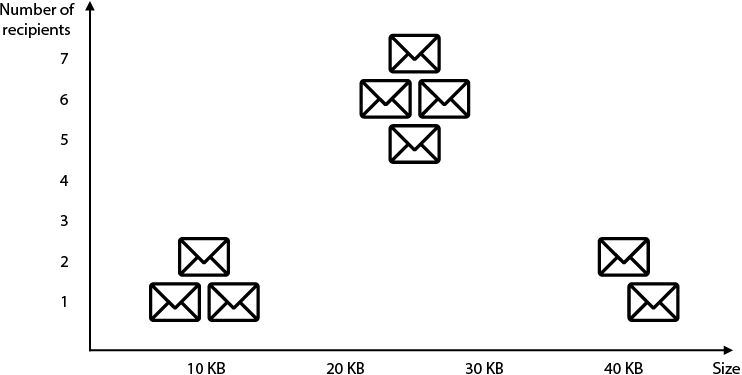
See how email size and recipient count form three visible clusters. section 2.3

















