Data exploration is the early, interactive work of finding available data, collecting and labeling it, cleaning it when needed, and shaping datasets around clear business requirements. It precedes prototyping and is critical because relevant data improves the likelihood of effective, efficient deep learning models. section 1.1.1
Use exploration to establish what can support model development:
- Search public and internal data sources, then collect, label, and organize candidate training data. section 1.1.1
- Inspect available data manually or with scripts and web-based analysis tools; early work need not have a formal collection pipeline. section 1.1.1
- Iterate between data exploration and experimental training to find an appropriate training-data shape and stabilize training code. section 10.1
- Track datasets, code versions, hyperparameters, metrics, and test results so experimental runs can be compared. section 1.2.3
Customer-support question answering
For a service that accepts natural-language customer questions and matches them to answers, data scientists first collect available training data and consult on algorithm choices. They then prototype several datasets, algorithms, and models before selecting a natural-language processing model for production onboarding. section 1.1.3
Figure 1.4 Data is pushed from sources or collectors, through the API to the data management service, where the data is further organized and stored in formats that are more friendly for model training.
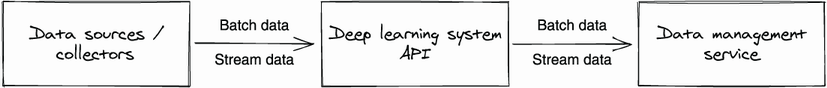
This architecture places exploration behind a user interface and API, with a data management service organizing collected data into forms friendlier for model training. section 1.2.3












