Kullback–Leibler divergence measures how different two probability distributions are. Soft distillation minimizes it to make a student model match the teacher’s full token distribution across the vocabulary. section 8.1
In the distillation workflow, KL divergence marks the difference between two supervision strategies:
- Hard distillation matches teacher-generated tokens and needs only generated text. section 8.1
- Soft distillation matches the teacher’s complete output distribution, including alternative tokens the teacher considers plausible, and requires logits or log probabilities. section 8.1
Teacher and student distributions
A large teacher produces a probability distribution for each next token. The smaller student is trained to reduce the KL divergence between its distribution and the teacher’s distribution. section 8.1
Figure 8.2 Hard distillation trains the student on teacher-generated tokens; soft distillation trains the student on the teacher’s full output distribution.
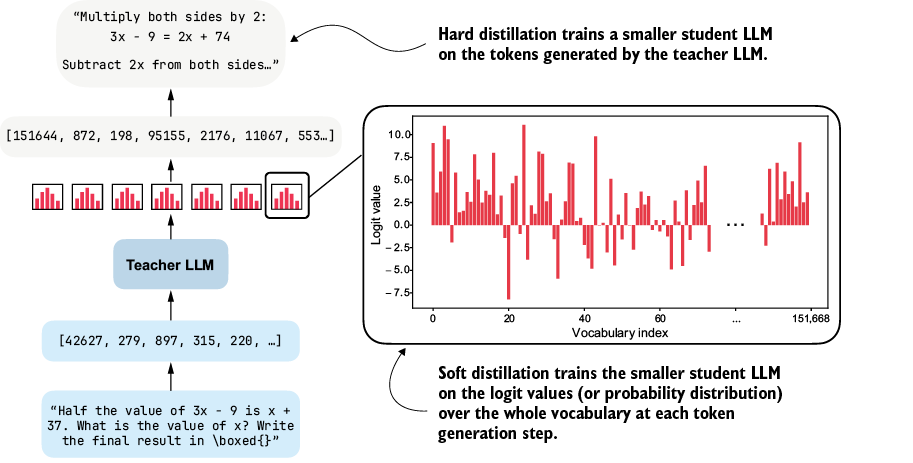
Compare hard distillation’s token targets with soft distillation’s full probability distributions. section 8.1











