Observability is the ability to infer a system’s internal behavior and health from emitted telemetry. In frontend work, it supports production monitoring, issue diagnosis, and incident response alongside automated testing. section 5.4
A practical observability approach combines:
- Structured logging for useful, searchable application events. section 5.4
- Real-time monitoring to reveal health and operational trends. section 5.4
- Client-side error tracking to detect and investigate frontend failures. section 5.4
- Telemetry and logs that support triage, reproduction, targeted fixes, and regression prevention. section 5.4
Production issue workflow
A team detects a frontend error through Sentry, inspects structured logs and monitoring data, reproduces the issue in a test environment, deploys a targeted fix, and adds a regression test or observability hook. section 5.4
Figure 5.8 Monitoring and observability strategy for a large-scale frontend application.
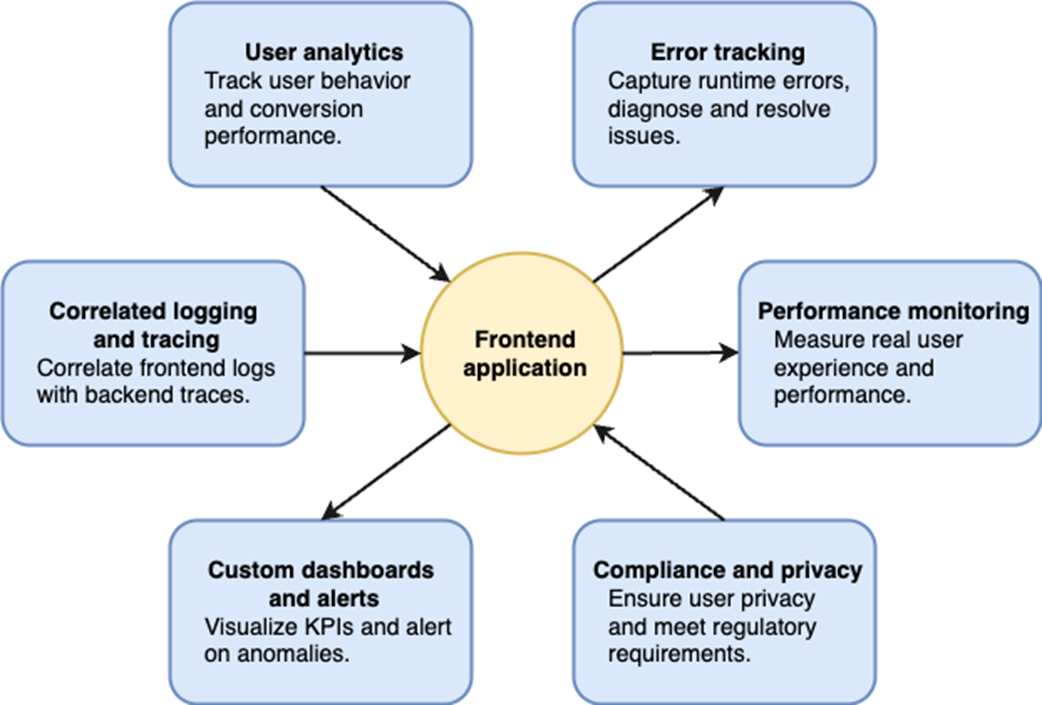
Maps monitoring and observability for a large-scale frontend application, helping connect telemetry sources with operational diagnosis. section 5.4
























