Reinforcement learning with human feedback (RLHF) aligns a language model using human preferences. It collects preference comparisons, trains a reward model to predict them, then uses PPO to optimize the policy while keeping it close to a reference policy. section 8.4
The pipeline chains three stages, each with distinct data and infrastructure demands:
- Collect human comparisons of response pairs. Robust reward models typically require tens of thousands of annotated pairs; disagreement between annotators makes multiple labels per pair valuable. section 8.4.1
- Train a reward model to predict preferences. If it overfits, the policy can exploit its errors instead of improving in ways people prefer. section 8.4.1
- Optimize the policy with PPO using the reward model as its signal. Tuning the learning rate, KL penalty, value-function coefficient, and clipping parameter is technically challenging. section 8.4.1
The practical burden is substantial: PPO training runs the policy, reference, reward, and value models together, requiring 3–5 times the GPU memory of standard fine-tuning. The full approach is estimated at $50,000–$200,000 and 8–16 weeks. Reserve it for fine-grained or open-ended preference generalization that binary preference pairs cannot capture; most enterprise teams are advised to try DPO first. section 8.4.1 section 8.7
Figure 8.6 RLHF’s three stages and four models versus DPO’s single supervised step.
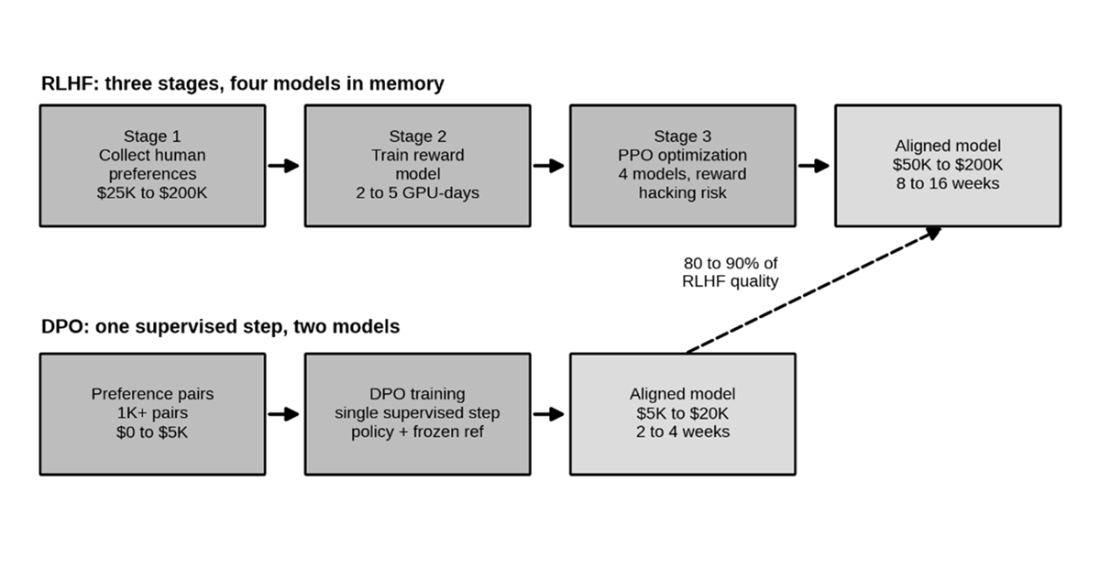
Compare RLHF’s three stages and four simultaneously loaded models with DPO’s single supervised step. section 8.4.1
Table 8.7 Preference optimization decision framework (incremental cost over an existing SFT model)
|
Goal
|
Technique
|
Cost
|
Timeline
|
Prerequisites
|
|
Quality/style alignment
|
DPO
|
$5K to $20K
|
2 to 4 weeks
|
1K+ preference pairs
|
|
Reasoning improvement
|
GRPO/RFT
|
$5K to $15K
|
2 to 4 weeks
|
Verifiable rewards
|
|
Maximum alignment
|
RLHF
|
$50K+
|
8 to 16 weeks
|
Tens of thousands of human labels
|
|
Frontier reasoning
|
SFT+GRPO
|
$20K to $50K
|
4 to 8 weeks
|
Domain expertise
|
Use the decision framework to compare RLHF with DPO, GRPO/RFT, and SFT+GRPO by goal, cost, timeline, and prerequisites. section 8.7

















