Why might one answer feel clearer, safer, or more helpful than another? Reinforcement learning from human feedback (RLHF) trains language models to reflect those preferences, not merely predict likely text. section 2.2.3
The process follows a simple loop:
- Generate multiple responses to the same prompt. section 2.2.3
- Have human reviewers rank them for helpfulness, clarity, accuracy, safety, and tone. section 2.2.3
- Train a reward model to score responses in ways that reflect those rankings. section 2.2.3
- Update the language model so preferred responses become more likely. section 2.2.3
A preference becomes a learned behavior
Reviewers may prefer a concise explanation over a confusing one, a polite refusal of dangerous instructions, or a direct answer over an evasive response. Repeated preferences shape learned guardrails rather than a manually written list of forbidden topics. section 2.2.3
Figure 2.8 The RLHF loop applied to a single prompt. The model generates two candidate responses; human reviewers rank them by helpfulness and clarity; a reward model learns that preference; the LLM is updated to make better responses more likely. The process repeats until the model's behavior aligns with human expectations.
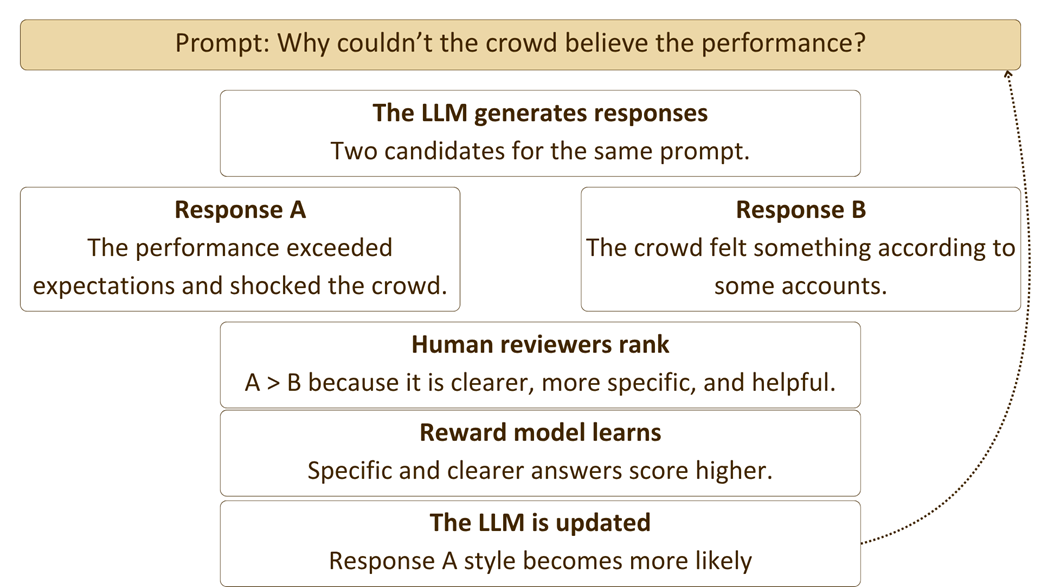
Follow the loop from candidate responses and human rankings to reward-model learning and language-model updates. section 2.2.3

















