Training fits a model’s parameters to data after a model family has been chosen. For a line, the parameters are its slope and intercept; training uses gradient descent to find values that reduce prediction error. section 16.4.1
In linear regression, a loss function sums squared vertical distances between predictions and observed values. The loss depends on the model parameters, so gradient descent updates them. Training uses a subset of the data; reserve other points for testing. section 16.4.1
Figure 16.19 The cost function of the example in figure 16.18 (B). Using the sum of squared errors, the cost is a function of m and b.
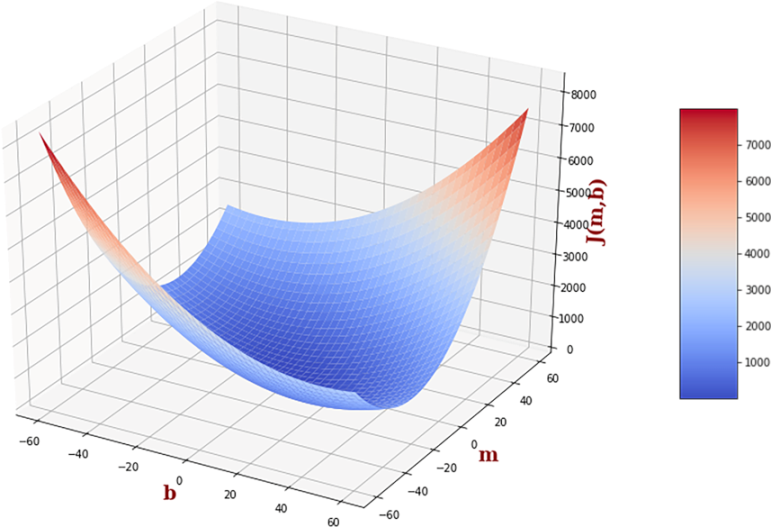
The cost surface shows how the sum of squared errors varies with a line’s slope and intercept. section 16.4.1























