Training adjusts a model’s parameters using examples so its predictions better match desired outcomes. In an artificial neural network (ANN), the adjustable parameters are weights; its architecture and configuration stay fixed during training. section 9.8
A basic ANN training loop:
- Initialize the weights; one option is to draw them from a normal distribution. section 9.8
- Run forward propagation on an example and compare the prediction with its actual class to calculate the cost, or prediction error. section 9.8
- Adjust the weights using gradient descent and the chain rule, then repeat until a chosen stopping condition is reached. section 9.8
A prediction error
If an ANN predicts 0.7 when the actual value is 1.0, the loss is 0.3. Training uses this error to guide weight adjustments. section 9.8
Figure 9.25 Example of adjusting a weight by using gradient descent
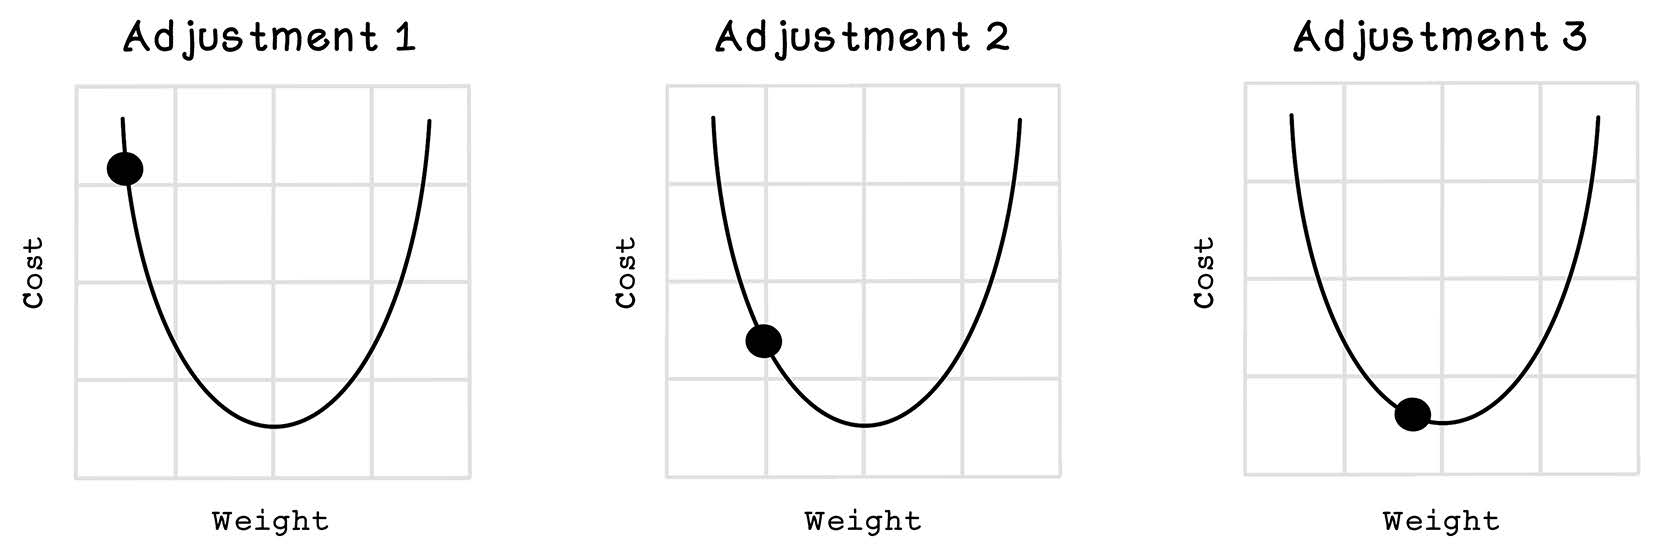
See how gradient descent adjusts a weight. section 9.8
An LLM workflow prepares text data, converts it into token IDs, uses self-attention to learn relationships among tokens, and decodes internal representations into language for predictions and generation. Training choices can also include Transformer configurations and attention heads. section 11.4
Figure 11.7 An overview of the LLM training workflow
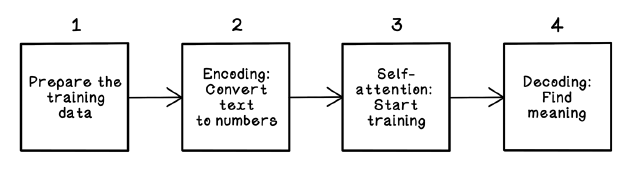
View the stages of the LLM training workflow. section 11.4























