Suppose a collection contains thousands of recipes and someone asks, “How can I make lasagna?” A vector database stores numerical representations of the recipes so a similarity search can retrieve relevant ones. In a retrieval-augmented generation (RAG) workflow, those recipes provide context for a language model’s answer. section 14.10.1 section 14.3
An embedding model converts recipe text into vectors. A simple flavor-space analogy places similar recipes near one another; real recipe embeddings instead represent relationships in language across many dimensions. At retrieval time, embed the question with the same model used for the stored recipes, then search for relevant documents. Cosine similarity compares vector direction, which is useful when recipes express similar meanings in different words. section 14.3 section 14.10.1
Figure 14.17 In the retrieval workflow, we can embed a user’s question and perform a similarity search in the database using cosine similarity. The vector database returns the documents that are most relevant to the question.
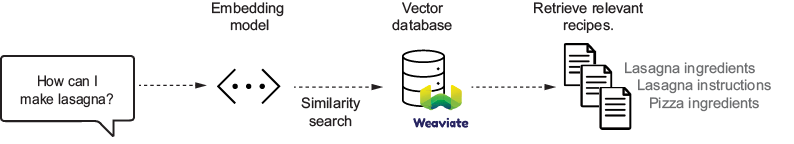
Follow the question from embedding through similarity search to the documents returned by the vector database. section 14.10.1
To keep a recipe collection usable, build and maintain it in task order:
- Load recipe files from MinIO, prepare records, and create a Weaviate collection with defined properties and an embedding configuration. section 14.10 section 14.6.1
- Compare incoming records with stored records using recipe names and chunk UUIDs. Mark new content for creation, changed content for updating, and identical content for omission. section 14.7
- Delete outdated records before uploading new and updated recipes. Airflow schedules and monitors the ingestion and update workflow. section 14.10 section 14.11
From stored recipe to answer
A user asks a recipe chat assistant for chocolate cookies. Python connects to a local Weaviate instance through a vector store and uses a retrieval chain with a chat model to generate an answer. The assistant can provide ingredients and steps for recipes in the collection; when a requested recipe is absent, it says it does not know that recipe. section 14.10.3
Collection setup is an operational choice: the example uses Weaviate and OpenAI’s text-embedding-3-large, with configuration paths for either the OpenAI API or an Azure endpoint. Updates also need an application-specific policy; the recipe workflow’s UUID comparison is one strategy, not a universal rule. Chunk size matters too: oversized chunks make sources harder to pinpoint, while undersized chunks can create inefficient queries and redundant sources. section 14.6.1 section 14.7 section 14.11

























