liveBook · Manning

Vector database

As explained in The Art of AI Product Development

A vector database is a database optimized for storing numeric vector representations and retrieving items by vector similarity.

A vector database stores numeric embeddings and makes them available for similarity-based retrieval. In semantic search, documents become vectors that preserve relationships in meaning rather than relying only on exact words. section 7.2.2

The underlying idea is distributional similarity: items appearing in similar contexts receive similar embeddings. A search system can therefore retrieve content whose meaning is close to a query, even when the wording differs. section 7.2.2

Similarity in embedding space

Embeddings for apple and banana are closer because they share contexts such as fruit, juice, and eating; car is farther away because its contexts differ. section 7.2.2

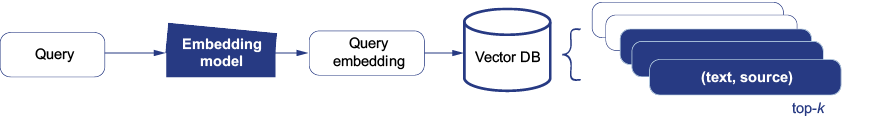
Figure 7.6 The process of semantic search
A diagram of a diagram

AI-generated content may be incorrect.

Trace how a query is transformed and matched against stored embeddings during semantic search. section 7.2.2


How The Art of AI Product Development covers it

How deep it goes
Explains distributional similarity and the storage-and-retrieval workflow, without detailing database internals.
Examples
Uses apple, banana, and car to illustrate distances between semantically similar and dissimilar embeddings.
What it assumes
Assumes basic database familiarity while teaching embeddings and distributional similarity from their semantic rationale.
What you can do after
Apply it via semantic search to retrieve documents whose meanings resemble a query.
How it connects
Links embeddings with semantic search and retrieval-augmented generation.

Also explained in

Compare how 26 books explain vector database →

Related concepts

This explainer was generated by Manning's knowledge graph from the text of The Art of AI Product Development. The section links point to the parts of the book it draws on.























