SQL is the executable language at the center of a Snowflake data pipeline: it loads staged files, combines staging data with target data, transforms records, and prepares results for downstream consumers. section 2.0 section 1.1.2
A practical pipeline applies SQL progressively:
- Stage a CSV file in a Snowflake internal stage, then load it into a staging table. section 2.0
- Merge rows from the staging table into the target table so the target model reflects incoming data. section 2.0
- Transform the loaded data into a format suitable for reporting and other downstream consumers. section 2.0
- Place SQL statements in a Snowflake task to run the pipeline on a recurring schedule; dependent tasks can form larger workflows. section 1.1.2
Daily bakery orders
A bakery collects email orders in a daily CSV file. SQL supports the operational flow from staged file to staging table, target-table merge, and transformed data for reporting; a scheduled task automates the run. section 2.0
Figure 2.1 Data pipeline that takes CSV files from a Snowflake internal stage, loads the data into a staging table, merges the data from the staging table into the target table, and transforms the data for downstream consumption
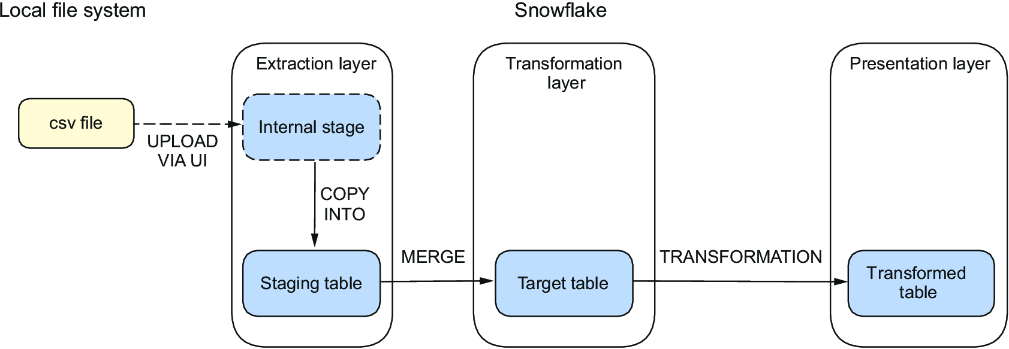
Follow the pipeline visually from a CSV file in a Snowflake internal stage through loading, merging, transformation, and downstream consumption. section 2.0
























