A training dataset is a collection of examples used to teach a learning method how to fit a model. Examples may include known outcome labels, and separate test data checks performance on new examples. section 8.10 section 1.21
Useful training data is prepared deliberately:
- Select data that matches the question or capability the model should learn. section 11.5
- Collect enough relevant examples, while prioritizing quality over sheer dataset size. section 11.6
- Clean and preprocess the examples so the learning method can use them consistently. section 11.5
- Check that the data can legally be used, especially when collecting online text or media. section 11.6
Predicting apartment prices
Suppose apartment prices depend partly on distance and number of rooms. A table containing real examples of those attributes and their prices becomes training data for fitting a linear regression model; separate examples later test predictions on unseen apartments. section 8.10
Teaching an image model
An image-generation dataset can pair images with captions, clean and standardize them, convert them into numerical representations, and add noise to create training examples. A diffusion model then learns to predict the added noise. section 12.3 section 12.27
Figure 11.8 First step (preparing training data) in the LLM training workflow
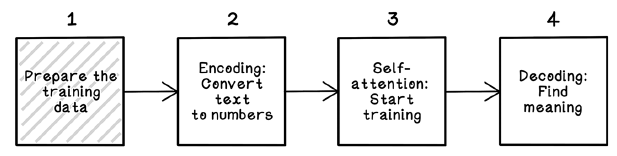
Use the workflow figure to place training-data preparation before the later stages of large-language-model training. section 11.5



































