A training dataset is data supplied during model training so the model can learn patterns or relationships. For large language models, dataset size and quality affect response quality, but adding more data is not automatically better. section 2.5.1 section 2.1
Useful training data must influence model probabilities sensibly and relate to the intended capability. In fine-tuning, teams set goals, prepare and format relevant data, tokenize it, and test the resulting model. Excessive token counts can exceed context length and affect training. section 2.5.1 section 12.3
When more data produces worse behavior
Training on the r/counting subreddit reportedly contributed to strange hallucinations in ChatGPT. The example illustrates why dataset composition and quality matter alongside quantity, especially when judging a model for practical use. section 2.5.1
Figure 2.1 Probability distribution in action
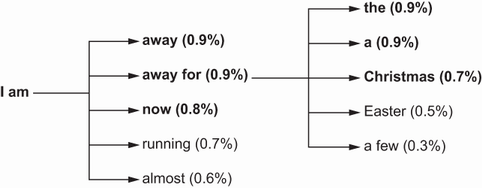
Use the probability-distribution figure to connect training data with the probabilistic nature of model outputs. section 2.1



































