A training dataset is the data used to fit a machine learning model. Treat it as an operational input to an iterative workflow: weak data quality can send work back from training or evaluation to data preparation. section 1.1.1
Production training datasets should support:
- Adequate quality and coverage, because data-related problems are among the most difficult ML lifecycle challenges. section 1.1.1 section 1.2.1
- Version control and lineage, so dataset access and model results remain reproducible. section 8.2
- Pipeline-compatible access rather than assumptions about local files or local storage. section 8.2
- Visible metrics and sanity checks that shorten feedback loops and support debugging. section 8.2
Pipeline-oriented dataset access
A training pipeline can retrieve data through a supported mechanism such as Kubeflow direct downloads, pass it into training code, and expose metrics through a dashboard. Designing for automated access instead of local files improves deployment readiness and later debugging. section 8.2
Figure 1.1 The experimentation phase of the ML life cycle
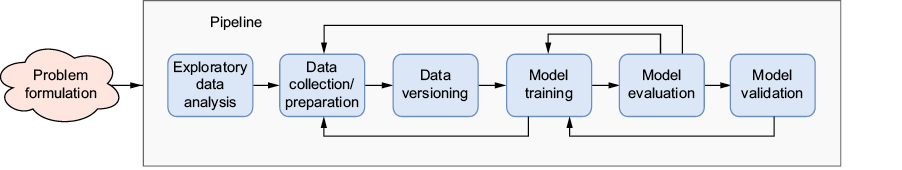
Use the experimentation lifecycle to trace how dataset quality affects preparation, training, evaluation, and repeated iteration. section 1.1.1



































