A training dataset is the collection of examples used to optimize a model during training. Its contents can shape model behavior and create risks that remain after deployment: models may reproduce sensitive passages, and fine-tuning can weaken safety behaviors even when the data is benign. section 4.4.1 section 6.6.3
Manage training data across the model lifecycle:
- Before training, deduplicate the corpus and remove or paraphrase material that should not appear in outputs. Deduplication reduces a common memorization risk, but a single occurrence can still be memorized. section 6.6.3
- After fine-tuning, test safety behavior rather than assuming proprietary tickets or documents are safe training data. Even benign domain datasets can weaken safeguards. section 4.4.1
- After release, use provider tools and add code licensing scanners or plagiarism detectors to build and release pipelines. Set review thresholds and log how flagged cases are resolved. section 6.6.3
Fine-tuning can erode safeguards
Llama-2 variants fine-tuned on PubMed abstracts, financial news, or legal opinions showed weaker safety behavior than their base model. The data was benign; the risk arose from fine-tuning rather than an attack. section 4.4.1
Figure 1.1 Generative models such as ChatGPT can often produce highly recognizable versions of famous artwork like the Mona Lisa. While this seems harmless, it illustrates the model's capacity to memorize and reconstruct images from its training data; a capability that becomes a serious privacy risk when the training data includes personal photographs.
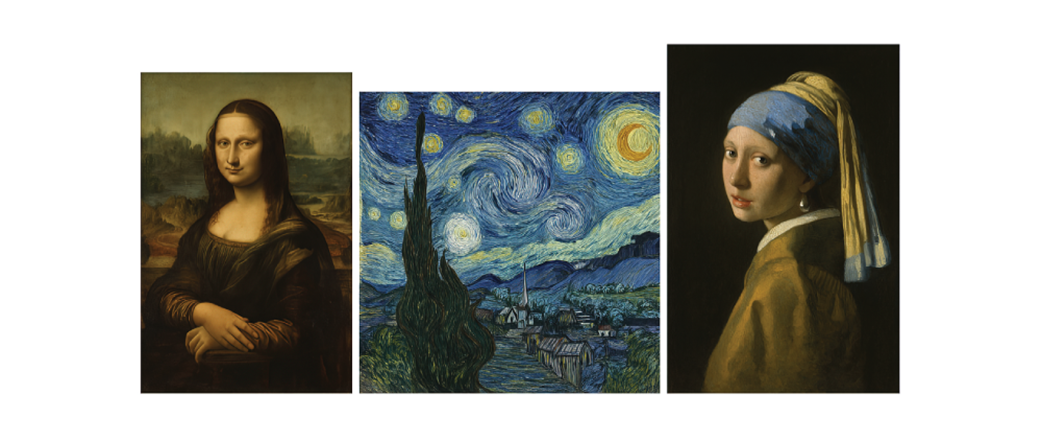
A recognizable reconstruction of the Mona Lisa illustrates how memorization can become a privacy risk when training data includes personal photographs. section 1.1
Upstream accountability also matters. Under the EU AI Act, providers of general-purpose AI models must maintain technical documentation and publish a summary of training data. section 1.1

















































